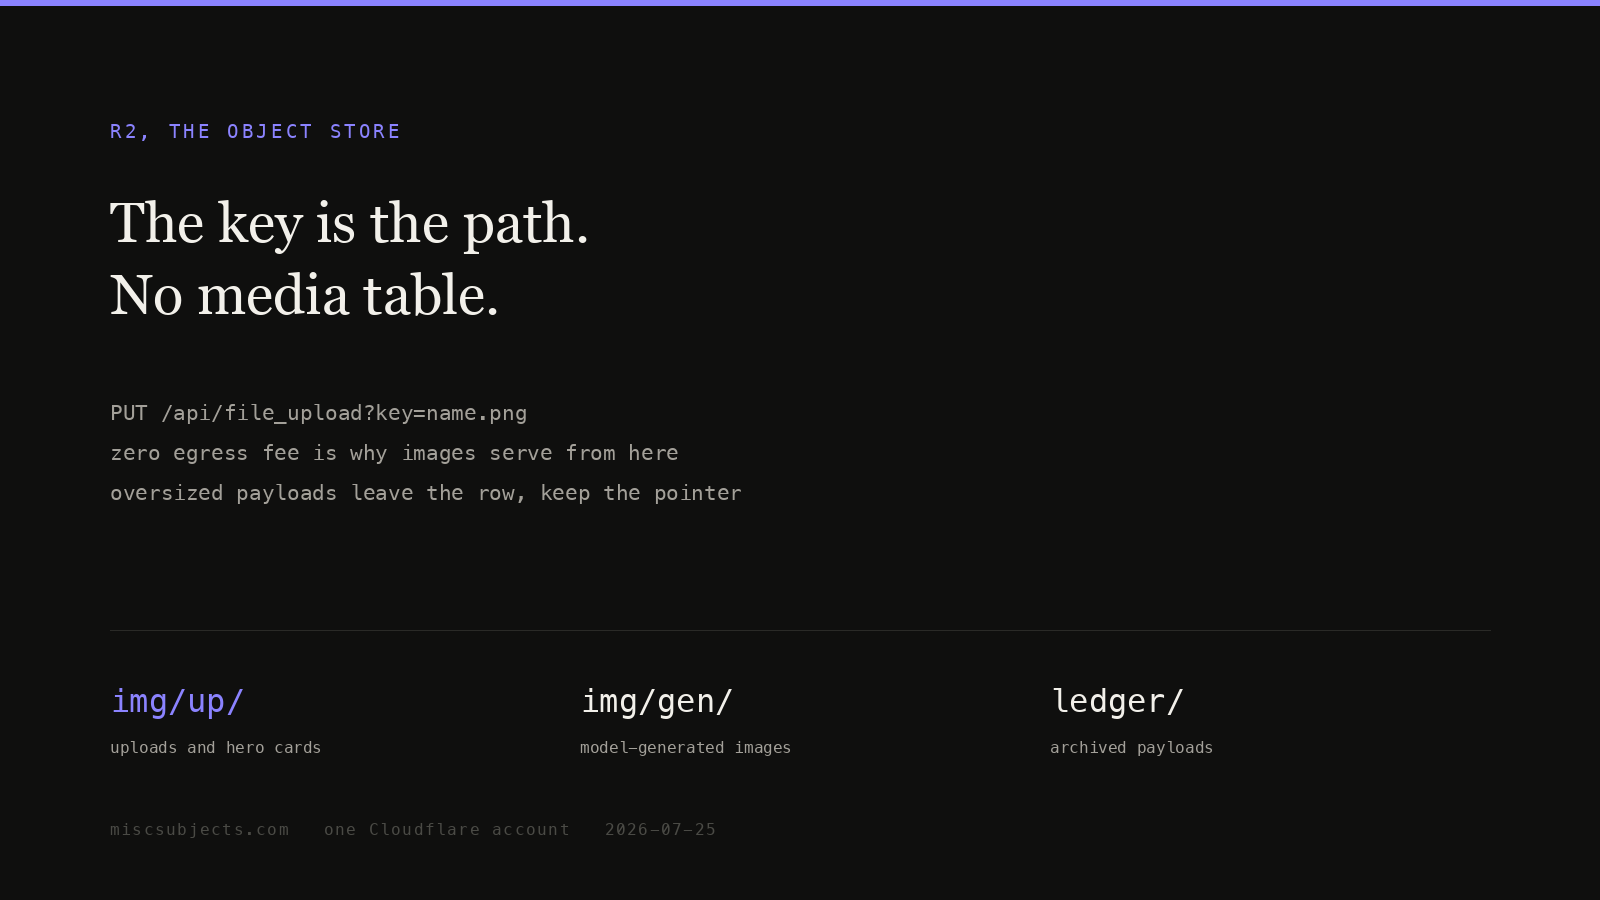
Cloudflare R2 pricing, S3 arithmetic, missing versioning, exact Worker code, and measured production behavior for deciding where files belong.
Cloudflare R2 is object storage: give it a key like img/up/hero.png and some bytes, and it hands them back on request. It speaks two dialects: the Amazon S3 HTTP API, so existing S3 tools work against it, and a native binding inside a Cloudflare Worker where the bucket is a JavaScript object with put, get, list and delete. Objects go to 5 TiB, keys to 1,024 bytes, and a bucket holds any number of them.
The reason anyone brings it up is the price of getting bytes out. Amazon charges for that. Cloudflare does not. The rest of this page is the arithmetic that follows, plus the things R2 will not do for you.
Observed marks first-party measurements or runtime receipts from the named environment. Derived marks arithmetic calculated from cited inputs. Specified marks vendor or standards documentation. Implemented and deployed name code and live-state evidence, respectively. Reproduced means the stated procedure was rerun. Externally attested marks operator reports; those reports show that an experience occurred, not that it is universal.
Zero egress is real; the meter is on the operations
R2 bills three things: how much you store, and two classes of API call. Class A operations change state: PutObject, CopyObject, ListObjects, CreateMultipartUpload, UploadPart, CompleteMultipartUpload. Class B operations read state: GetObject, HeadObject, HeadBucket. Deletes are free. Bandwidth to the internet is free.
Rates, read from the pricing page on 2026-07-26:
Standard
Infrequent Access
Storage
$0.015 / GB-month
$0.01 / GB-month
Class A (writes, lists)
$4.50 / million
$9.00 / million
Class B (reads)
$0.36 / million
$0.90 / million
Data retrieval
none
$0.01 / GB
Egress to the internet
free
free
Free each month
10 GB-month, 1M Class A, 10M Class B
none; the free tier is Standard only
Minimum storage duration
none
30 days
Cloudflare rounds usage up to the next unit: 1,000,001 operations bills as two million, 1.1 GB-month bills as 2 GB-month.
He is describing the meter correctly and drawing the wrong conclusion. Price the overage. Class B beyond the free 10 million costs $0.36 per additional million. On the ten-terabyte workload computed below, the S3 egress line is $891.00. For R2's metered operations to cost that much, you would have to make 2.475 billion Class B calls beyond the free allowance in one month: 891 ÷ 0.36 × 1,000,000. The class-ops meter is real. It is roughly three orders of magnitude away from being the thing that costs you money.
Serving 10 TB a month: $18.45 on R2, $923.00 on S3
The workload: 1,000 GB stored, average object 500 KB (so 2,000,000 objects), 200,000 new objects written during the month, and 10,000 GB served to the public internet, or 20,000,000 GET requests. S3 prices are us-east-1, pulled from the AWS Price List API on 2026-07-26: Standard storage $0.023/GB-month, Tier-1 requests (PUT, COPY, POST, LIST) $0.005 per 1,000, Tier-2 requests (GET and all others) $0.0004 per 1,000, data transfer out to the internet $0.09/GB for the first 10 TB beyond the 100 GB monthly free allowance.
Line
R2 arithmetic
R2
S3 arithmetic
S3
Storage
(1,000 − 10 free) × $0.015
$14.85
1,000 × $0.023
$23.00
Writes
200,000 of 1,000,000 free
$0.00
200,000 × $0.005/1,000
$1.00
Reads
(20,000,000 − 10,000,000) × $0.36/M
$3.60
20,000,000 × $0.0004/1,000
$8.00
Egress
10,000 GB, unmetered
$0.00
(10,000 − 100) × $0.09
$891.00
Total
$18.45
$923.00
Fifty times cheaper, and the ratio is almost entirely one line: egress is 96.5% of the S3 bill. The table also shows that R2's operation rates are not a gimmick to claw the egress back. Class A at $4.50/million undercuts S3's Tier-1 at $5.00/million, and Class B at $0.36/million undercuts Tier-2 at $0.40/million. R2 is 10% cheaper per call and free on bandwidth.
Two published totals for real public-serving workloads, both itemised. A 33 GB WordPress plugin mirror on R2 plus Workers, and a full archive of every SEC filing served at roughly twice the SEC's own volume:
Neither workload needed versioning, and neither was cold. That is why they land where they do.
The workload where S3 wins is the one you never read
R2 has exactly two storage classes. S3 has a ladder that goes much colder. For a write-once archive that is almost never read and never leaves the cloud, the egress advantage is worth nothing and the storage floor decides.
The workload: 100,000 GB (100 TB) of compliance records, written once, read a handful of times a year, consumed inside the same cloud.
Where it sits
Rate
Monthly
R2 Standard
(100,000 − 10) × $0.015
$1,499.85
R2 Infrequent Access
100,000 × $0.01 (no free tier applies)
$1,000.00
S3 Glacier Flexible Retrieval
100,000 × $0.0036
$360.00
S3 Deep Archive Access tier
100,000 × $0.00099
$99.00
R2's cheapest class costs 2.8× the Glacier Flexible rate and 10.1× the Deep Archive rate. There is no colder tier to move to; Standard and Infrequent Access are the whole ladder. If your bytes are cold and captive, stay on S3.
Infrequent Access pays only below about one read every two months
Infrequent Access looks like a third off the storage price. The retrieval fee eats it almost immediately. Take a 1 GB object held for one month and read r times:
Standard: $0.015 + r × $0.00000036
Infrequent Access: $0.010 + r × $0.0000009 + r × 1 GB × $0.01
Set them equal: 0.005 = 0.01000054r, so r ≈ 0.5. The retrieval fee is 99.99% of the right-hand side; the operation-rate difference is noise. A 1 GB object must be read less than once every two months for Infrequent Access to be cheaper. Add the 30-day minimum billing duration, where you pay a full month even if you delete on day two, and the class is for backups and cold originals, nothing else.
Move objects there with a lifecycle rule rather than by hand. The transition itself is billed as a Class A operation.
Lifecycle rules also delete: an expiration rule on a prefix is how an ingest bucket stops growing forever, and how incomplete multipart uploads get cleaned up. They expire after 7 days by default. A bucket accepts up to 1,000 rules.
The S3 compatibility table marks PutBucketVersioning, GetBucketVersioning, PutObjectLockConfiguration and GetObjectLockConfiguration all unsupported. Versioning and Object Lock are the two standard defences against ransomware and against a human running the wrong script; R2 offers neither in S3's form.
It does have bucket locks, a per-prefix retention rule blocking deletion and overwriting for a fixed period or indefinitely, enforced with 10069 / ObjectLockedByBucketPolicy and HTTP 403. That stops deletion. It does not give you "fetch me yesterday's copy".
For that you write versioning yourself: never overwrite a key, always write a new one, keep a pointer.
js
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
// Content-addressed writes: the key carries the version, so nothing is ever overwritten.exportasyncfunction putVersioned(env, logicalKey, body, contentType) {
const bytes = body instanceof ArrayBuffer ? body : new TextEncoder().encode(body);
const digest = await crypto.subtle.digest('SHA-256', bytes);
const hash = [...new Uint8Array(digest)].map(b => b.toString(16).padStart(2, '0')).join('');
const versionKey = `${logicalKey}/${Date.now()}-${hash.slice(0, 12)}`;
await env.R2.put(versionKey, bytes, { httpMetadata: { contentType } });
// The pointer is one small object; reading it is one Class B call.await env.R2.put(`${logicalKey}/current`, versionKey, {
httpMetadata: { contentType: 'text/plain' },
});
return { versionKey, hash };
}
exportasyncfunction getCurrent(env, logicalKey) {
const ptr = await env.R2.get(`${logicalKey}/current`);
if (!ptr) returnnull;
return env.R2.get(await ptr.text()); // second Class B call
}
Line 19, Column 1JavaScript
The cost of doing it this way: every read is two Class B operations instead of one, and old versions accumulate until a lifecycle rule expires them. At $0.36 per million reads, the doubled read is $0.36 per million objects fetched. That is the actual price of the missing feature.
The free-egress trust question, answered from the terms
The sharpest objection is not about the price list but about whether it is load-bearing.
The worry points at a real clause, and the clause says the opposite of what it assumes. Cloudflare's Service-Specific Terms restrict the CDN on Free, Pro and Business plans: "Unless you are an Enterprise customer, Cloudflare offers specific Paid Services (e.g., the Developer Platform, Images, and Stream) that you must use in order to serve video and other large files via the CDN." The Developer Platform named there is the thing R2 belongs to. Using R2 to serve large files is the compliant path, not the risky one.
The Developer Platform section carries its own limit, and it is a different kind: "Cloudflare may temporarily limit your storage and/or the number of requests you can make or receive using the Developer Platform if processing such requests would put an undue burden on the Cloudflare network." Rate limiting, stated in advance. Not a retroactive per-GB bill.
Verdict: the enforcement risk on R2 is throttling under abnormal load, not an undisclosed egress charge. The pricing page's footnote is unambiguous: "Egressing directly from R2, including via the Workers API, S3 API, and r2.dev domains does not incur data transfer (egress) charges and is free." What it does not cover is metered services you bolt on top; those bill separately.
Note the trap in that table: list is a Class A operation, priced 12.5× a read. A paginated file browser that lists on every page view burns the expensive quota, not the cheap one.
A single put accepts up to 5 GiB. Above that, multipart, or you get 100100 / EntityTooLarge:
js
1
2
3
4
5
6
7
const upload = await env.R2.createMultipartUpload('big/archive.tar');
const parts = [];
let n = 1;
for (const chunk of chunksOf(stream, 16 * 1024 * 1024)) {   // 16 MiB, uniform
  parts.push(await upload.uploadPart(n++, chunk));
}
await upload.complete(parts);
Line 7, Column 1JavaScript
From outside a Worker, use the S3 API against https://<ACCOUNT_ID>.r2.cloudflarestorage.com with region: "auto", or hand a browser a presigned URL so it uploads straight to R2 without the bytes passing through your server:
js
1
2
3
4
5
6
7
8
9
import { AwsClient } from'aws4fetch';
const r2 = new AwsClient({ accessKeyId: ACCESS_KEY_ID, secretAccessKey: SECRET_ACCESS_KEY });
const url = new URL(`https://${ACCOUNT_ID}.r2.cloudflarestorage.com/my-bucket/uploads/${name}`);
url.searchParams.set('X-Amz-Expires', '3600'); // secondsconst signed = await r2.sign(new Request(url, { method: 'PUT' }), {
aws: { signQuery: true, service: 's3' },
});
// signed.url is safe to hand to a browser; it expires in one hour.
Line 9, Column 1JavaScript
Tamper with any signature parameter and the request fails with 10035 / SignatureDoesNotMatch; let it age out and you get 10018 / ExpiredRequest.
Serving an object publicly, and the header that decides your bill
Three ways to make a bucket readable from the internet. A custom domain puts it behind a hostname on your zone, the only option that gets Cloudflare Cache, WAF rules and Bot Management. An r2.dev subdomain is one toggle, documented as non-production. A Worker route gives you the object plus whatever logic you put in front of it. The third, in nine lines:
The URL path is the object key: no media table, no second name for a file, and a rename is a copy.
cache-control: public, max-age=31536000 is the line that matters financially. Cached responses never reach R2, so they cost no Class B operation. Fetched live, the header comes back on the wire:
A one-year max-age is only safe because a changed image is written under a new key, never patched in place. Serve mutable objects this way and you will serve stale bytes for a year.
When a row outgrows D1, the bytes move to R2 and the row keeps a pointer
D1, the SQLite database in the same account (D1 as the spine), has a hard per-value ceiling: 2,000,000 bytes for any string, BLOB or row. Exceed it and every write to that row fails with D1_ERROR: string or blob too big, the driver's rendering of SQLite's SQLITE_TOOBIG.
This application hit that wall storing article revision history. Each write snapshots the previous version — full body, claims and sources — into a JSON blob on the row. One article's metadata reached 2,068,258 bytes across 24 snapshots, 68,258 over the cap, and from then on every write to it returned HTTP 500.
The fix generalises into a rule: when a field outgrows its row, the field moves to object storage and the row keeps a pointer plus a hash. The pointer is small and fixed-size; the hash is what makes the pointer trustworthy.
The key format is one line in functions/_lib/revisions_r2.js:
js
1
2
const PREFIX = "revisions/";
function r2Key(slug, n) { return`${PREFIX}${slug}/${n}.json`; }
Line 2, Column 1JavaScript
So revision 3 of this article lives at revisions/cloudflare-os-r2/3.json. What stays in D1 is a nine-field index entry, written by the same function:
prev_hash and hash are the point: the chain is verifiable from D1 alone, no R2 read needed to prove the history has not been edited, while the bytes are fetched only when someone asks for a specific revision. That 2,068,258-byte row became 206,362 bytes, and the original revision is still retrievable.
Measured across the bucket today: 4,930 objects under revisions/, 148,075,146 bytes, 1,053 distinct articles, mean 30,036 bytes per revision. The largest single history, revisions/bpc-157/, is 119 objects and 14,503,688 bytes — 7.25× the D1 row cap, so that article alone would be permanently unwritable under the old scheme.
Proof the offload preserved the history rather than truncating it:
Two failure modes worth naming: KV used as a database (eventually consistent, so a read after a write may return the old value), and R2 used as a database (no query, only a lexicographic key scan at Class A prices).
Symptom, cause, fix
Symptom
Cause
Fix
no R2 binding / no R2, HTTP 500
The Worker deployed without the r2_buckets entry, or the bucket does not exist yet
npx wrangler r2 bucket create <name>, then confirm the [[r2_buckets]] block is present in every environment, including [[env.preview.r2_buckets]]
10006 / NoSuchBucket, HTTP 404
Bucket name typo, or the bucket is in a different account
npx wrangler r2 bucket list and compare byte for byte
get() returns null instead of throwing
Not an error — the Workers API returns null for a missing key rather than raising NoSuchKey
Branch on null; do not wrap in try/catch and expect a throw
100100 / EntityTooLarge, HTTP 400
Single-part upload over 5 GiB
Switch to createMultipartUpload; parts uniform and ≥ 5 MiB
10011 / EntityTooSmall or 10048 / InvalidPart, HTTP 400
A non-final part under 5 MiB, or parts of differing sizes
Every part except the last must be ≥ 5 MiB and identical in size
10058 / TooManyRequests, HTTP 429
More than one write per second to the same key
Shard the key, or funnel writes for that key through a Durable Object
10035 / SignatureDoesNotMatch, HTTP 403
A presigned URL was edited, or the secret is wrong
Regenerate; check URL encoding of the key
10069 / ObjectLockedByBucketPolicy, HTTP 403
A bucket lock retention rule covers that prefix
Wait out the retention period; a lock is not overridable
D1_ERROR: string or blob too big on a write that used to work
A JSON column crossed D1's 2,000,000-byte per-value cap
Offload the heavy field to R2, keep a pointer and a hash in the row
wrangler r2 object put --file fails with fetch failed
Reported against Wrangler 3.74.0 and still open
Pipe the file instead: `cat f.txt \
Multipart complete() returns empty customMetadata in production but not in wrangler dev
Open bug, reported against Wrangler 3.57.2
Re-read with head() after completing; the metadata is stored, only the return value drops it
How the numbers on this page were measured
Four measurements, taken 2026-07-26 against the live production bucket from a laptop served by the San Jose edge (cf-ray suffix SJC).
1 — Buckets and inventory.npx wrangler r2 bucket list returns three buckets: loop-data-raw (2026-05-31), miscsubjects-ledger (2026-06-09), miscsubjects-store (2026-06-16). The inventory of miscsubjects-ledger was walked through the authenticated list route, 1,000 keys per page, following the cursor:
62 pages, 41,809 objects, 3,904,595,147 bytes (3.64 GiB) — under the 10 GB free allowance, so today's storage line is $0.00. By prefix: events/ 34,258 objects / 2,241 MB; revisions/ 4,930 / 148 MB; img/gen/ 387 / 765 MB; img/up/ 191 / 432 MB; docs/ 1,332 / 9.5 MB. The walk itself cost 62 Class A operations.
2 — Put and get latency. A 65,536-byte JSON object written and read six times each over one reused TLS connection, at the deliberately-named temporary key tmp/measure-2026-07-25-delete-me.json, then deleted — DELETE returned {"ok":true,...,"deleted":true} and a follow-up list of tmp/ returned zero objects.
PUT round trips: 535, 587, 634, 737, 801, 2,471 ms — median 686 ms. GET: 96, 104, 125, 148, 185, 192 ms — median 136 ms. These are full client-to-edge-to-R2-to-client times through the Worker, not R2's internal service time; the first request in each series carries the TLS handshake, 86 ms and 71 ms.
3 — Public object headers.curl -sI https://miscsubjects.com/img/up/cloudflare-os-r2-hero-card.png returned HTTP 200, content-length: 51205, content-type: image/png, cache-control: public, max-age=31536000, cf-cache-status: MISS. Full body fetch, 189 ms.
4 — A revision read out of R2.curl -s "https://miscsubjects.com/api/articles/cloudflare-os-r2?rev=0" returned rev: 0, is_head: false, prev_hash: "genesis", hash: 24915ae889f6184140a56e89d476d28a31e0cf0e28d31c0990c2aab6f7a626fc, body length 2,878 — out of revisions/cloudflare-os-r2/0.json, not the database. Account identifiers are omitted throughout; the S3 endpoint appears as <ACCOUNT_ID>.r2.cloudflarestorage.com.
R2 total for the worked 1 TB stored and 10 TB served month
$923.00
S3 total for the same worked month in us-east-1
2.475B
paid Class B calls needed to equal the worked S3 egress line
<0.5
reads per month where a 1 GB object favors Infrequent Access
41,809
objects in the measured production bucket
3.64 GiB
bytes in the measured production bucket
It's not mentioned, but important to note, that R2 lacks object versioning.— kevlened, Hacker News
References (27)
Cloudflare R2 pricing — Cloudflare, Jul 26, 2026“There are no charges for egress bandwidth for any storage class.”
How R2 works — Cloudflare, Jul 26, 2026“Cloudflare R2 is an S3-compatible object storage service with no egress fees, built on Cloudflare's global network.”
Workers R2 API reference — Cloudflare, Jul 26, 2026“R2 writes are strongly consistent. Once the Promise resolves, all subsequent read operations will see this key value pair globally.”
S3 API compatibility — Cloudflare, Jul 26, 2026“When using the S3 API, the region for an R2 bucket is auto”
R2 storage classes — Cloudflare, Jul 26, 2026“Infrequent Access storage is ideal for data that is accessed less frequently.”
R2 object lifecycles — Cloudflare, Jul 26, 2026“Object lifecycles determine the retention period of objects uploaded to your bucket and allow you to specify when objects should transition from Standard storage to Infrequent Access storage.”
R2 bucket locks — Cloudflare, Jul 26, 2026“Bucket locks prevent the deletion and overwriting of objects in an R2 bucket for a specified period — or indefinitely.”
R2 public buckets — Cloudflare, Jul 26, 2026“Expose your bucket using a Cloudflare-managed https://r2.dev subdomain for non-production use cases.”
R2 presigned URLs — Cloudflare, Jul 26, 2026“Presigned URLs are generated client-side with no communication with R2, requiring only your R2 API credentials and an implementation of the AWS Signature Version 4 signing algorithm.”
Durable Objects limits — Cloudflare, Jul 26, 2026“Each SQLite-backed Durable Object has a storage limit of 10 GB on a Workers Paid plan.”
Cloudflare Developer Platform terms — Cloudflare, Jul 26, 2026“Cloudflare may temporarily limit your storage and/or the number of requests you can make or receive using the Developer Platform if processing such requests would put an undue burden on the Cloudflare network”
Clarify presigned URL docs — GitHub — cloudflare/cloudflare-docs, Jan 22, 2025“I did notice that after reading through the entire documentation and those linked pages.”
Cloud object storage benchmark — AIMultiple, Jun 16, 2026“All tests ran from Europe against each provider’s EU-region endpoint.”
The next chapter for Cloudflare Workers: open-source — Hacker News, May 9, 2022“So, with R2 you get unlimited egress, 500x the free limit on requests and flat global pricing. Oh, and the actual storage is cheaper.”
How Canva saves Amazon S3 costs — Hacker News, Jun 19, 2023“See the Docker x Cloudflare case study where improving cache-hit ratio by 2% (by moving to R2) decreased S3 egress fee by 66%”
WordPress Plugin Mirror Downloader (Proof of Concept) — Hacker News, Oct 6, 2024“All up, it would be US$5.35/month starting costs which will rise as number of WordPress plugins and Worker usage increases as outlined here. Cloudflare CDN bandwidth is free of charge, so no need to worry about egress bandwidth fees.”
Ask HN: S3(AWS) vs R2(CF)–Which is better? — Hacker News, Apr 9, 2026“R2's zero egress pricing is genuinely compelling for anything serving large files publicly - media, assets, user uploads. If your use case is "store stuff and serve it to users," R2 wins on cost.”
Hetzner continues its growth in the US with a new location — Hacker News, Dec 5, 2022“They claim $0 egress fees, but their free "Class A operations (mutate state)" and "Class B operations (read state)" have a mothly cap. After that you pay by the number. Isn't that an egress free?”
Comparing AWS S3 with Cloudflare R2: Price, Performance and User Experience — Hacker News, Nov 27, 2024“Is R2 egress actually free, or is it like CFs CDN egress which is "free" until they arbitrarily decide you're using it too much or using it for the wrong things so now you have to pay $undisclosed per GB?”
{
"schema":"http://google-preview.miscsubjects.com/schemas/jarticle.json",
"status":"published",
"slug":"cloudflare-os-r2",
"title":"R2 cuts a 10 TB delivery bill from $923 to $18.45",
"kind":"essay",
"summary":"Cloudflare R2 pricing, S3 arithmetic, missing versioning, exact Worker code, and measured production behavior for deciding where files belong.",
"created":"2026-07-26T03:59:25.307Z",
"body": [
"Cloudflare R2 is object storage: give it a key like `img/up/hero.png` and some bytes, and it hands them back on request. It speaks two dialects: the Amazon S3 HTTP API, so existing S3 tools work against it, and a native binding inside a Cloudflare Worker where the bucket is a JavaScript object with `put`, `get`, `list` and `delete`. Objects go to 5 TiB, keys to 1,024 bytes, and a bucket holds any number of them.\n\nThe reason anyone brings it up is the price of getting bytes *out*. Amazon charges for that. Cloudflare does not. The rest of this page is the arithmetic that follows, plus the things R2 will not do for you.",
{
"type":"source",
"id":"s2"
},
"## Evidence status\n\n**Observed** marks first-party measurements or runtime receipts from the named environment.\n**Derived** marks arithmetic calculated from cited inputs. **Specified** marks vendor or standards\ndocumentation. **Implemented** and **deployed** name code and live-state evidence, respectively.\n**Reproduced** means the stated procedure was rerun. **Externally attested** marks operator reports;\nthose reports show that an experience occurred, not that it is universal.\n\n## Zero egress is real; the meter is on the operations\n\nR2 bills three things: how much you store, and two classes of API call. **Class A** operations change state: `PutObject`, `CopyObject`, `ListObjects`, `CreateMultipartUpload`, `UploadPart`, `CompleteMultipartUpload`. **Class B** operations read state: `GetObject`, `HeadObject`, `HeadBucket`. Deletes are free. Bandwidth to the internet is free.\n\nRates, read from the pricing page on 2026-07-26:\n\n| | Standard | Infrequent Access |\n| --- | --- | --- |\n| Storage | $0.015 / GB-month | $0.01 / GB-month |\n| Class A (writes, lists) | $4.50 / million | $9.00 / million |\n| Class B (reads) | $0.36 / million | $0.90 / million |\n| Data retrieval | none | $0.01 / GB |\n| Egress to the internet | free | free |\n| Free each month | 10 GB-month, 1M Class A, 10M Class B | none; the free tier is Standard only |\n| Minimum storage duration | none | 30 days |\n\nCloudflare rounds usage up to the next unit: 1,000,001 operations bills as two million, 1.1 GB-month bills as 2 GB-month.",
{
"type":"source",
"id":"s1"
},
"A reader of that same page put the obvious objection plainly.",
{
"type":"source",
"id":"s21"
},
"He is describing the meter correctly and drawing the wrong conclusion. Price the overage. Class B beyond the free 10 million costs $0.36 per additional million. On the ten-terabyte workload computed below, the S3 egress line is $891.00. For R2's metered operations to cost that much, you would have to make **2.475 billion** Class B calls beyond the free allowance in one month: 891 ÷ 0.36 × 1,000,000. The class-ops meter is real. It is roughly three orders of magnitude away from being the thing that costs you money.\n\n## Serving 10 TB a month: $18.45 on R2, $923.00 on S3\n\nThe workload: 1,000 GB stored, average object 500 KB (so 2,000,000 objects), 200,000 new objects written during the month, and 10,000 GB served to the public internet, or 20,000,000 GET requests. S3 prices are `us-east-1`, pulled from the AWS Price List API on 2026-07-26: Standard storage $0.023/GB-month, Tier-1 requests (PUT, COPY, POST, LIST) $0.005 per 1,000, Tier-2 requests (GET and all others) $0.0004 per 1,000, data transfer out to the internet $0.09/GB for the first 10 TB beyond the 100 GB monthly free allowance.\n\n| Line | R2 arithmetic | R2 | S3 arithmetic | S3 |\n| --- | --- | --- | --- | --- |\n| Storage | (1,000 − 10 free) × $0.015 | $14.85 | 1,000 × $0.023 | $23.00 |\n| Writes | 200,000 of 1,000,000 free | $0.00 | 200,000 × $0.005/1,000 | $1.00 |\n| Reads | (20,000,000 − 10,000,000) × $0.36/M | $3.60 | 20,000,000 × $0.0004/1,000 | $8.00 |\n| Egress | 10,000 GB, unmetered | $0.00 | (10,000 − 100) × $0.09 | $891.00 |\n| **Total** | | **$18.45** | | **$923.00** |\n\nFifty times cheaper, and the ratio is almost entirely one line: egress is 96.5% of the S3 bill. The table also shows that R2's operation rates are not a gimmick to claw the egress back. Class A at $4.50/million undercuts S3's Tier-1 at $5.00/million, and Class B at $0.36/million undercuts Tier-2 at $0.40/million. R2 is 10% cheaper per call *and* free on bandwidth.",
{
"type":"source",
"id":"s15"
},
"Cloudflare's CTO stated the free-tier gap when R2 launched, and the allowances he named still hold on the page fetched today.",
{
"type":"source",
"id":"s19"
},
"Two published totals for real public-serving workloads, both itemised. A 33 GB WordPress plugin mirror on R2 plus Workers, and a full archive of every SEC filing served at roughly twice the SEC's own volume:",
{
"type":"source",
"id":"s24"
},
{
"type":"source",
"id":"s26"
},
"Neither workload needed versioning, and neither was cold. That is why they land where they do.\n\n## The workload where S3 wins is the one you never read\n\nR2 has exactly two storage classes. S3 has a ladder that goes much colder. For a write-once archive that is almost never read and never leaves the cloud, the egress advantage is worth nothing and the storage floor decides.\n\nThe workload: 100,000 GB (100 TB) of compliance records, written once, read a handful of times a year, consumed inside the same cloud.\n\n| Where it sits | Rate | Monthly |\n| --- | --- | --- |\n| R2 Standard | (100,000 − 10) × $0.015 | $1,499.85 |\n| R2 Infrequent Access | 100,000 × $0.01 (no free tier applies) | $1,000.00 |\n| S3 Glacier Flexible Retrieval | 100,000 × $0.0036 | $360.00 |\n| S3 Deep Archive Access tier | 100,000 × $0.00099 | $99.00 |\n\nR2's cheapest class costs 2.8× the Glacier Flexible rate and 10.1× the Deep Archive rate. There is no colder tier to move to; Standard and Infrequent Access are the whole ladder. If your bytes are cold and captive, stay on S3.",
{
"type":"source",
"id":"s5"
},
"The person who ran both and stayed on AWS drew the boundary in one sentence.",
{
"type":"source",
"id":"s22"
},
"## Infrequent Access pays only below about one read every two months\n\nInfrequent Access looks like a third off the storage price. The retrieval fee eats it almost immediately. Take a 1 GB object held for one month and read `r` times:\n\n- Standard: `$0.015 + r × $0.00000036`\n- Infrequent Access: `$0.010 + r × $0.0000009 + r × 1 GB × $0.01`\n\nSet them equal: `0.005 = 0.01000054r`, so `r ≈ 0.5`. The retrieval fee is 99.99% of the right-hand side; the operation-rate difference is noise. **A 1 GB object must be read less than once every two months for Infrequent Access to be cheaper.** Add the 30-day minimum billing duration, where you pay a full month even if you delete on day two, and the class is for backups and cold originals, nothing else.\n\nMove objects there with a lifecycle rule rather than by hand. The transition itself is billed as a Class A operation.\n\n```bash\nnpx wrangler r2 bucket lifecycle add miscsubjects-ledger \\\n --name \"archive-old-events\" \\\n --prefix \"events/\" \\\n --storage-class InfrequentAccess \\\n --transition-days 30\n```\n\nLifecycle rules also delete: an expiration rule on a prefix is how an ingest bucket stops growing forever, and how incomplete multipart uploads get cleaned up. They expire after 7 days by default. A bucket accepts up to 1,000 rules.",
{
"type":"source",
"id":"s6"
},
"## R2 will not keep the old version of an object\n\nThis is the gap that costs people data. When you `put` to a key that already exists, the previous bytes are gone.",
{
"type":"source",
"id":"s23"
},
"The S3 compatibility table marks `PutBucketVersioning`, `GetBucketVersioning`, `PutObjectLockConfiguration` and `GetObjectLockConfiguration` all unsupported. Versioning and Object Lock are the two standard defences against ransomware and against a human running the wrong script; R2 offers neither in S3's form.",
{
"type":"source",
"id":"s4"
},
"It does have **bucket locks**, a per-prefix retention rule blocking deletion and overwriting for a fixed period or indefinitely, enforced with `10069 / ObjectLockedByBucketPolicy` and HTTP 403. That stops deletion. It does not give you \"fetch me yesterday's copy\".",
{
"type":"source",
"id":"s7"
},
"For that you write versioning yourself: never overwrite a key, always write a new one, keep a pointer.\n\n```js\n// Content-addressed writes: the key carries the version, so nothing is ever overwritten.\nexport async function putVersioned(env, logicalKey, body, contentType) {\n const bytes = body instanceof ArrayBuffer ? body : new TextEncoder().encode(body);\n const digest = await crypto.subtle.digest('SHA-256', bytes);\n const hash = [...new Uint8Array(digest)].map(b => b.toString(16).padStart(2, '0')).join('');\n const versionKey = `${logicalKey}/${Date.now()}-${hash.slice(0, 12)}`;\n await env.R2.put(versionKey, bytes, { httpMetadata: { contentType } });\n // The pointer is one small object; reading it is one Class B call.\n await env.R2.put(`${logicalKey}/current`, versionKey, {\n httpMetadata: { contentType: 'text/plain' },\n });\n return { versionKey, hash };\n}\n\nexport async function getCurrent(env, logicalKey) {\n const ptr = await env.R2.get(`${logicalKey}/current`);\n if (!ptr) return null;\n return env.R2.get(await ptr.text()); // second Class B call\n}\n```\n\nThe cost of doing it this way: every read is two Class B operations instead of one, and old versions accumulate until a lifecycle rule expires them. At $0.36 per million reads, the doubled read is $0.36 per million objects fetched. That is the actual price of the missing feature.\n\n## The free-egress trust question, answered from the terms\n\nThe sharpest objection is not about the price list but about whether it is load-bearing.",
{
"type":"source",
"id":"s25"
},
"The worry points at a real clause, and the clause says the opposite of what it assumes. Cloudflare's Service-Specific Terms restrict the **CDN** on Free, Pro and Business plans: *\"Unless you are an Enterprise customer, Cloudflare offers specific Paid Services (e.g., the Developer Platform, Images, and Stream) that you must use in order to serve video and other large files via the CDN.\"* The Developer Platform named there is the thing R2 belongs to. Using R2 to serve large files is the compliant path, not the risky one.\n\nThe Developer Platform section carries its own limit, and it is a different kind: *\"Cloudflare may temporarily limit your storage and/or the number of requests you can make or receive using the Developer Platform if processing such requests would put an undue burden on the Cloudflare network.\"* Rate limiting, stated in advance. Not a retroactive per-GB bill.\n\nVerdict: the enforcement risk on R2 is throttling under abnormal load, not an undisclosed egress charge. The pricing page's footnote is unambiguous: *\"Egressing directly from R2, including via the Workers API, S3 API, and r2.dev domains does not incur data transfer (egress) charges and is free.\"* What it does not cover is metered services you bolt on top; those bill separately.",
{
"type":"source",
"id":"s14"
},
"## Every call, and which meter it hits\n\nBind the bucket first. In `wrangler.toml`:\n\n```toml\n[[r2_buckets]]\nbinding = \"R2\"\nbucket_name = \"miscsubjects-ledger\"\n```\n\n`binding` is the variable name your code sees; `bucket_name` is the real bucket. Create the bucket before the first deploy, or the binding fails:\n\n```bash\nnpx wrangler r2 bucket create miscsubjects-ledger\nnpx wrangler r2 bucket list\n```\n\n| Call | What it does | Meter |\n| --- | --- | --- |\n| `env.R2.put(key, value, opts)` | Stores bytes; returns an `R2Object`. Strongly consistent: once the promise resolves, every reader worldwide sees it | Class A |\n| `env.R2.get(key, opts)` | Returns `R2ObjectBody` with `.body` as a stream, or `null` if absent | Class B |\n| `env.R2.head(key)` | Metadata only, no body, or `null` | Class B |\n| `env.R2.list(opts)` | Up to 1,000 keys, lexicographic, `opts.prefix` to scope | Class A |\n| `env.R2.delete(key or key[])` | Up to 1,000 keys per call | free |\n| `env.R2.createMultipartUpload(key)` | Starts a multipart upload | Class A |\n| `upload.uploadPart(n, body)` | One part; all non-final parts must be the same size and ≥ 5 MiB | Class A each |\n| `upload.complete(parts)` | Finishes it | Class A |",
{
"type":"source",
"id":"s3"
},
"Note the trap in that table: **`list` is a Class A operation**, priced 12.5× a read. A paginated file browser that lists on every page view burns the expensive quota, not the cheap one.\n\nA single `put` accepts up to 5 GiB. Above that, multipart, or you get `100100 / EntityTooLarge`:\n\n```js\nconst upload = await env.R2.createMultipartUpload('big/archive.tar');\nconst parts = [];\nlet n = 1;\nfor (const chunk of chunksOf(stream, 16 * 1024 * 1024)) { // 16 MiB, uniform\n parts.push(await upload.uploadPart(n++, chunk));\n}\nawait upload.complete(parts);\n```\n\nFrom outside a Worker, use the S3 API against `https://<ACCOUNT_ID>.r2.cloudflarestorage.com` with `region: \"auto\"`, or hand a browser a presigned URL so it uploads straight to R2 without the bytes passing through your server:\n\n```js\nimport { AwsClient } from 'aws4fetch';\n\nconst r2 = new AwsClient({ accessKeyId: ACCESS_KEY_ID, secretAccessKey: SECRET_ACCESS_KEY });\nconst url = new URL(`https://${ACCOUNT_ID}.r2.cloudflarestorage.com/my-bucket/uploads/${name}`);\nurl.searchParams.set('X-Amz-Expires', '3600'); // seconds\nconst signed = await r2.sign(new Request(url, { method: 'PUT' }), {\n aws: { signQuery: true, service: 's3' },\n});\n// signed.url is safe to hand to a browser; it expires in one hour.\n```\n\nTamper with any signature parameter and the request fails with `10035 / SignatureDoesNotMatch`; let it age out and you get `10018 / ExpiredRequest`.",
{
"type":"source",
"id":"s9"
},
"## Serving an object publicly, and the header that decides your bill\n\nThree ways to make a bucket readable from the internet. A **custom domain** puts it behind a hostname on your zone, the only option that gets Cloudflare Cache, WAF rules and Bot Management. An **r2.dev subdomain** is one toggle, documented as non-production. A **Worker route** gives you the object plus whatever logic you put in front of it. The third, in nine lines:",
{
"type":"source",
"id":"s8"
},
"```js\n// functions/img/[[path]].js: every /img/* URL is an R2 key.\nexport async function onRequestGet(context) {\n const { params, env } = context;\n const key = 'img/' + (Array.isArray(params.path) ? params.path.join('/') : String(params.path || ''));\n if (!env.R2) return new Response('no R2', { status: 500 });\n const obj = await env.R2.get(key);\n if (!obj) return new Response('not found', { status: 404 });\n const ct = obj.httpMetadata?.contentType || 'image/png';\n return new Response(obj.body, { headers: { 'content-type': ct, 'cache-control': 'public, max-age=31536000' } });\n}\n```\n\nThe URL path *is* the object key: no media table, no second name for a file, and a rename is a copy.\n\n`cache-control: public, max-age=31536000` is the line that matters financially. Cached responses never reach R2, so they cost no Class B operation. Fetched live, the header comes back on the wire:\n\n```text\n$ curl -sI https://miscsubjects.com/img/up/cloudflare-os-r2-hero-card.png\nHTTP/2 200\ncontent-type: image/png\ncontent-length: 51205\ncache-control: public, max-age=31536000\ncf-cache-status: MISS\ncf-ray: a210b8bcbb715616-SJC\n```\n\nA one-year max-age is only safe because a changed image is written under a new key, never patched in place. Serve mutable objects this way and you will serve stale bytes for a year.",
{
"type":"source",
"id":"s17"
},
"Cache-hit ratio is not a rounding error on the bill:",
{
"type":"source",
"id":"s20"
},
"## When a row outgrows D1, the bytes move to R2 and the row keeps a pointer\n\nD1, the SQLite database in the same account ([D1 as the spine](/a/cloudflare-os-d1)), has a hard per-value ceiling: **2,000,000 bytes** for any string, BLOB or row. Exceed it and every write to that row fails with `D1_ERROR: string or blob too big`, the driver's rendering of SQLite's `SQLITE_TOOBIG`.\n\nThis application hit that wall storing article revision history. Each write snapshots the previous version — full body, claims and sources — into a JSON blob on the row. One article's metadata reached **2,068,258 bytes** across 24 snapshots, 68,258 over the cap, and from then on every write to it returned HTTP 500.\n\nThe fix generalises into a rule: **when a field outgrows its row, the field moves to object storage and the row keeps a pointer plus a hash.** The pointer is small and fixed-size; the hash is what makes the pointer trustworthy.\n\nThe key format is one line in `functions/_lib/revisions_r2.js`:\n\n```js\nconst PREFIX = \"revisions/\";\nfunction r2Key(slug, n) { return `${PREFIX}${slug}/${n}.json`; }\n```\n\nSo revision 3 of this article lives at `revisions/cloudflare-os-r2/3.json`. What stays in D1 is a nine-field index entry, written by the same function:\n\n```js\nreturn {\n n: full.n, ts: full.ts, title: full.title, status: full.status,\n register: full.register, bytes: full.body.length,\n prev_hash: full.prev_hash, hash: full.hash,\n r2_key: key,\n};\n```\n\n`prev_hash` and `hash` are the point: the chain is verifiable from D1 alone, no R2 read needed to prove the history has not been edited, while the bytes are fetched only when someone asks for a specific revision. That 2,068,258-byte row became **206,362 bytes**, and the original revision is still retrievable.",
{
"type":"source",
"id":"s16"
},
"Measured across the bucket today: 4,930 objects under `revisions/`, 148,075,146 bytes, 1,053 distinct articles, mean 30,036 bytes per revision. The largest single history, `revisions/bpc-157/`, is 119 objects and 14,503,688 bytes — 7.25× the D1 row cap, so that article alone would be permanently unwritable under the old scheme.\n\nProof the offload preserved the history rather than truncating it:\n\n```bash\n$ curl -s \"https://miscsubjects.com/api/articles/cloudflare-os-r2?rev=0\" | jq '{rev,is_head,prev_hash,body_len:(.body|length)}'\n{ \"rev\": 0, \"is_head\": false, \"prev_hash\": \"genesis\", \"body_len\": 2878 }\n```\n\nThat body came out of R2. Nothing but the index is in the database.\n\n## Choosing between R2, S3, KV, D1 and Durable Object storage\n\n| Workload | Put it in | Why, and the limit that decides it |\n| --- | --- | --- |\n| Images, video, uploads, anything served to the public internet | **R2** | Free egress; 5 TiB per object; strongly consistent |\n| Cold archive, rarely read, consumed inside AWS | **S3 Glacier** | $0.0036–$0.00099/GB-month against R2's $0.01 floor |\n| A file with a legal retention requirement and a need to read yesterday's copy | **S3** | R2 has bucket locks but no object versioning |\n| Small values read constantly from many places — flags, prompts, rendered snapshots | **Workers KV** | Values to 25 MiB, but eventually consistent and 1 write/second per key |\n| Anything you need to query, join, filter or index | **D1** | 10 GB per database, 2 MB per value; a bucket cannot answer `WHERE` |\n| Per-entity state needing serialized writes and coordination | **Durable Object storage** | 10 GB per object, single-threaded execution ([the Workers layer](/a/cloudflare-os-workers)) |\n| A row that has outgrown 2 MB | **R2, with a pointer in D1** | The offload pattern above |\n| Blobs written and read once, under 25 MiB, with no need for a URL | **either KV or R2** | R2 unless you need sub-millisecond reads at the edge |",
{
"type":"source",
"id":"s10"
},
{
"type":"source",
"id":"s11"
},
{
"type":"source",
"id":"s12"
},
{
"type":"source",
"id":"s13"
},
"Two failure modes worth naming: KV used as a database (eventually consistent, so a read after a write may return the old value), and R2 used as a database (no query, only a lexicographic key scan at Class A prices).\n\n## Symptom, cause, fix\n\n| Symptom | Cause | Fix |\n| --- | --- | --- |\n| `no R2 binding` / `no R2`, HTTP 500 | The Worker deployed without the `r2_buckets` entry, or the bucket does not exist yet | `npx wrangler r2 bucket create <name>`, then confirm the `[[r2_buckets]]` block is present in every environment, including `[[env.preview.r2_buckets]]` |\n| `10006 / NoSuchBucket`, HTTP 404 | Bucket name typo, or the bucket is in a different account | `npx wrangler r2 bucket list` and compare byte for byte |\n| `get()` returns `null` instead of throwing | Not an error — the Workers API returns `null` for a missing key rather than raising `NoSuchKey` | Branch on `null`; do not wrap in `try/catch` and expect a throw |\n| `100100 / EntityTooLarge`, HTTP 400 | Single-part upload over 5 GiB | Switch to `createMultipartUpload`; parts uniform and ≥ 5 MiB |\n| `10011 / EntityTooSmall` or `10048 / InvalidPart`, HTTP 400 | A non-final part under 5 MiB, or parts of differing sizes | Every part except the last must be ≥ 5 MiB and identical in size |\n| `10058 / TooManyRequests`, HTTP 429 | More than one write per second to the same key | Shard the key, or funnel writes for that key through a Durable Object |\n| `10035 / SignatureDoesNotMatch`, HTTP 403 | A presigned URL was edited, or the secret is wrong | Regenerate; check URL encoding of the key |\n| `10069 / ObjectLockedByBucketPolicy`, HTTP 403 | A bucket lock retention rule covers that prefix | Wait out the retention period; a lock is not overridable |\n| `D1_ERROR: string or blob too big` on a write that used to work | A JSON column crossed D1's 2,000,000-byte per-value cap | Offload the heavy field to R2, keep a pointer and a hash in the row |\n| `wrangler r2 object put --file` fails with `fetch failed` | Reported against Wrangler 3.74.0 and still open | Pipe the file instead: `cat f.txt \\| npx wrangler r2 object put bucket/f.txt --pipe` |\n| Multipart `complete()` returns empty `customMetadata` in production but not in `wrangler dev` | Open bug, reported against Wrangler 3.57.2 | Re-read with `head()` after completing; the metadata is stored, only the return value drops it |\n\n## How the numbers on this page were measured\n\nFour measurements, taken 2026-07-26 against the live production bucket from a laptop served by the San Jose edge (`cf-ray` suffix `SJC`).",
{
"type":"source",
"id":"s27"
},
"**1 — Buckets and inventory.** `npx wrangler r2 bucket list` returns three buckets: `loop-data-raw` (2026-05-31), `miscsubjects-ledger` (2026-06-09), `miscsubjects-store` (2026-06-16). The inventory of `miscsubjects-ledger` was walked through the authenticated list route, 1,000 keys per page, following the cursor:\n\n```bash\ncurl -s -H \"x-terminal-key: $TERMINAL_KEY\" \\\n \"https://miscsubjects.com/api/r2/?list=1&limit=1000&cursor=$CURSOR\"\n```\n\n62 pages, **41,809 objects, 3,904,595,147 bytes (3.64 GiB)** — under the 10 GB free allowance, so today's storage line is $0.00. By prefix: `events/` 34,258 objects / 2,241 MB; `revisions/` 4,930 / 148 MB; `img/gen/` 387 / 765 MB; `img/up/` 191 / 432 MB; `docs/` 1,332 / 9.5 MB. The walk itself cost 62 Class A operations.\n\n**2 — Put and get latency.** A 65,536-byte JSON object written and read six times each over one reused TLS connection, at the deliberately-named temporary key `tmp/measure-2026-07-25-delete-me.json`, then deleted — `DELETE` returned `{\"ok\":true,...,\"deleted\":true}` and a follow-up list of `tmp/` returned zero objects.\n\n```bash\ncurl -s -X PUT \"https://miscsubjects.com/api/r2/tmp/measure-2026-07-25-delete-me.json\" \\\n -H \"x-terminal-key: $TERMINAL_KEY\" -H 'content-type: application/json' \\\n --data-binary @probe.json -w \"%{time_total}\\n\"\n```\n\nPUT round trips: 535, 587, 634, 737, 801, 2,471 ms — median **686 ms**. GET: 96, 104, 125, 148, 185, 192 ms — median **136 ms**. These are full client-to-edge-to-R2-to-client times through the Worker, not R2's internal service time; the first request in each series carries the TLS handshake, 86 ms and 71 ms.\n\n**3 — Public object headers.** `curl -sI https://miscsubjects.com/img/up/cloudflare-os-r2-hero-card.png` returned HTTP 200, `content-length: 51205`, `content-type: image/png`, `cache-control: public, max-age=31536000`, `cf-cache-status: MISS`. Full body fetch, 189 ms.",
{
"type":"source",
"id":"s18"
},
"**4 — A revision read out of R2.** `curl -s \"https://miscsubjects.com/api/articles/cloudflare-os-r2?rev=0\"` returned `rev: 0`, `is_head: false`, `prev_hash: \"genesis\"`, `hash: 24915ae889f6184140a56e89d476d28a31e0cf0e28d31c0990c2aab6f7a626fc`, body length 2,878 — out of `revisions/cloudflare-os-r2/0.json`, not the database. Account identifiers are omitted throughout; the S3 endpoint appears as `<ACCOUNT_ID>.r2.cloudflarestorage.com`.\n\nThe index for the rest of this stack is [the Cloudflare account as an operating system](/a/cloudflare-os)."
],
"facts": {
"converted_from":"markdown",
"original_updated":"2026-07-26T05:59:18.921Z",
"register":"essay",
"category":null
},
"hero":"https://miscsubjects.com/img/up/cloudflare-os-r2-hero-card.png",
"model":"Opus 5 (Claude Code)",
"tags": [
"cloudflare",
"architecture",
"r2",
"cloudflare-os"
],
"sources": [
{
"id":"s1",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/pricing/",
"title":"Cloudflare R2 pricing",
"quote":"There are no charges for egress bandwidth for any storage class.",
"summary":"The current Standard and Infrequent Access storage, operation, retrieval, free-tier and rounding rates.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c1",
"c2",
"c3",
"c4",
"c5",
"c8",
"c9"
],
"quote_sha256":"7c36166683a3ec15e4f171c6fe1597e923225f377618ccef69dbec4c50d01202"
},
{
"id":"s2",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/how-r2-works/",
"title":"How R2 works",
"quote":"Cloudflare R2 is an S3-compatible object storage service with no egress fees, built on Cloudflare's global network.",
"summary":"Defines R2, its interfaces and its strong-consistency architecture.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c9"
],
"quote_sha256":"6f0a4161288705fd826052b40e14b0d1d3abc67201345d59896566375df9abc7"
},
{
"id":"s3",
"type":"specification",
"url":"https://developers.cloudflare.com/r2/api/workers/workers-api-reference/",
"title":"Workers R2 API reference",
"quote":"R2 writes are strongly consistent. Once the Promise resolves, all subsequent read operations will see this key value pair globally.",
"summary":"The exact binding methods, limits and consistency contract used by the runnable examples.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c10",
"c13",
"c7",
"c9"
],
"quote_sha256":"ddcb4e94bb8ef6f420af29c9b1bd5bee25dd9fdcc96aa5a3e4c679bdcd9cdb4a"
},
{
"id":"s4",
"type":"specification",
"url":"https://developers.cloudflare.com/r2/api/s3/api/",
"title":"S3 API compatibility",
"quote":"When using the S3 API, the region for an R2 bucket is auto",
"summary":"The implemented and unsupported S3 operations, including the absent versioning and Object Lock calls.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c6"
],
"quote_sha256":"e9ea24f1142295839ead4c87731527477c859b8a06bd4196939e4be5097361c9"
},
{
"id":"s5",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/buckets/storage-classes/",
"title":"R2 storage classes",
"quote":"Infrequent Access storage is ideal for data that is accessed less frequently.",
"summary":"Documents the retrieval fee and 30-day minimum that determine when Infrequent Access pays.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c4",
"c5"
],
"quote_sha256":"087478eed06153010364f467bf062753853323e1c16c760ddada005acfa79b3a"
},
{
"id":"s6",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/buckets/object-lifecycles/",
"title":"R2 object lifecycles",
"quote":"Object lifecycles determine the retention period of objects uploaded to your bucket and allow you to specify when objects should transition from Standard storage to Infrequent Access storage.",
"summary":"The transition and expiration rules used to control cold storage and stale multipart uploads.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c5",
"c7"
],
"quote_sha256":"0ac227bb8047aa1baa5d1a6d00fedc94635ac542e4e874a55ee4f95c7b9f33af"
},
{
"id":"s7",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/buckets/bucket-locks/",
"title":"R2 bucket locks",
"quote":"Bucket locks prevent the deletion and overwriting of objects in an R2 bucket for a specified period — or indefinitely.",
"summary":"The retention control R2 offers in place of S3 Object Lock, and its exact boundary.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c6"
],
"quote_sha256":"8412d709adab9863a08f49a2cf682c9bb97e9a9cec61af1d60d485618b42cfe2"
},
{
"id":"s8",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/buckets/public-buckets/",
"title":"R2 public buckets",
"quote":"Expose your bucket using a Cloudflare-managed https://r2.dev subdomain for non-production use cases.",
"summary":"The three public-serving paths and the non-production status of r2.dev.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c12"
],
"quote_sha256":"4db15aee5729022f158a28cc6e0b6aa68bd3513928cb45c3a8f4f2cf3109263a"
},
{
"id":"s9",
"type":"specification",
"url":"https://developers.cloudflare.com/r2/api/s3/presigned-urls/",
"title":"R2 presigned URLs",
"quote":"Presigned URLs are generated client-side with no communication with R2, requiring only your R2 API credentials and an implementation of the AWS Signature Version 4 signing algorithm.",
"summary":"The exact signing model for direct browser uploads and expiring downloads.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c11"
],
"quote_sha256":"64980a90e31350d6659f93ffd9c2aa15888b1c691bba75b6684982e8d6948c3a"
},
{
"id":"s10",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/r2/platform/limits/",
"title":"R2 limits",
"quote":"5 GiB (single-part) / 4.995 TiB (multi-part)",
"summary":"The current object, key, metadata, multipart and managed-public-bucket limits.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c10",
"c12",
"c15"
],
"quote_sha256":"cff1fd11b3d2d8475f340bbbc1c786549c8938c883327eacf0f71dbb5f361477"
},
{
"id":"s11",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/kv/platform/limits/",
"title":"Workers KV limits",
"quote":"25 MiB",
"summary":"The maximum KV value size used in the storage decision table.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c15"
],
"quote_sha256":"a8c4da05d6869c6934c73a9205d5cfbe1e1cc99d0b7a1b722c7bf262c7c8421c"
},
{
"id":"s12",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/d1/platform/limits/",
"title":"D1 limits",
"quote":"2,000,000 bytes (2 MB)",
"summary":"The exact D1 string, BLOB and row ceiling behind the R2 offload pattern.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c14",
"c15"
],
"quote_sha256":"3dc92a69108bcbdb1a3a792fa78926cba07916a4823c8434bfaafe0d79df7d5b"
},
{
"id":"s13",
"type":"publisher_documentation",
"url":"https://developers.cloudflare.com/durable-objects/platform/limits/",
"title":"Durable Objects limits",
"quote":"Each SQLite-backed Durable Object has a storage limit of 10 GB on a Workers Paid plan.",
"summary":"The per-object storage ceiling used in the storage decision table.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c15"
],
"quote_sha256":"d7de1de7c843e05703487388a30460880027c84283be2247d6f6b32c4014b3e2"
},
{
"id":"s14",
"type":"publisher_documentation",
"url":"https://www.cloudflare.com/service-specific-terms-developer-platform/",
"title":"Cloudflare Developer Platform terms",
"quote":"Cloudflare may temporarily limit your storage and/or the number of requests you can make or receive using the Developer Platform if processing such requests would put an undue burden on the Cloudflare network",
"summary":"The contractual boundary for Developer Platform rate limiting.",
"publisher":"Cloudflare",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c8"
],
"quote_sha256":"bce1ba5c5fbf04dba0b4040bc89f92e02cca03b498927a4e3eabc486a51e2295"
},
{
"id":"s15",
"type":"specification",
"url":"https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonS3/current/us-east-1/index.json",
"title":"AWS S3 us-east-1 Price List API",
"quote":"$0.023 per GB - first 50 TB / month of storage used",
"summary":"Machine-readable AWS storage and request rates used in the 1 TB plus 10 TB comparison.",
"publisher":"Amazon Web Services",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c2",
"c3",
"c4"
],
"quote_sha256":"c017ef60aa6218fbb9f86136bfbb9c3f155411f720de5866b8bc79dbdd7a008f"
},
{
"id":"s16",
"type":"github",
"url":"https://github.com/cloudflare/cloudflare-docs/issues/19190",
"title":"Clarify presigned URL docs",
"quote":"I did notice that after reading through the entire documentation and those linked pages.",
"summary":"A repository issue showing a real presigned-URL integration failure and the documentation repair.",
"publisher":"GitHub — cloudflare/cloudflare-docs",
"author":"harshil1712",
"date":"2025-01-22",
"claim_ids": [
"c11",
"c7"
],
"quote_sha256":"df1e90faf5f17789659312e45409434b1a954c1af6bd7379657f8d83b9a6386c"
},
{
"id":"s17",
"type":"github",
"url":"https://github.com/cloudflare/workers-sdk/issues/3520",
"title":"Unable to put an object with a key containing three dots to R2",
"quote":"Failed to fetch /accounts/*/r2/buckets/*/objects/assets/_...slug_.abcd1234.css - 403: Forbidden",
"summary":"A minimal Wrangler/R2 path-handling failure, visible in the product repository issue tracker.",
"publisher":"GitHub — cloudflare/workers-sdk",
"author":"tkngaejcpi",
"date":"2023-06-25",
"claim_ids": [
"c12"
],
"quote_sha256":"764860c1fba8df9cfc02e486d0756457142262fa50a105d49e93f365af7f48ce"
},
{
"id":"s18",
"type":"independent_measurement",
"url":"https://aimultiple.com/cloud-object-storage",
"title":"Cloud object storage benchmark",
"quote":"All tests ran from Europe against each provider’s EU-region endpoint.",
"summary":"An independent five-provider benchmark with geography, file sizes, throughput and latency published with its method.",
"publisher":"AIMultiple",
"author":"Sedat Dogan",
"date":"2026-06-16",
"claim_ids": [
"c17"
],
"quote_sha256":"cb9db2f2ba6466b29a00d60f5ab9154cafc30371077a6842ffc307b3615b4224"
},
{
"id":"s19",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=31314273",
"title":"The next chapter for Cloudflare Workers: open-source",
"quote":"So, with R2 you get unlimited egress, 500x the free limit on requests and flat global pricing. Oh, and the actual storage is cheaper.",
"summary":"Cloudflare's CTO laying out the free-tier comparison against S3 with exact numbers (10M vs 20k GETs, 1M vs 2k PUTs, unlimited vs 100GB egress). Positive, and a vendor employee speaking first-hand rather than a docs page.",
"publisher":"Hacker News",
"author":"jgrahamc",
"date":"2022-05-09",
"claim_ids": [
"c1"
],
"quote_sha256":"108218cd3e2857d9df3e36e618e18ceaacc6ce9b9e7568f0dd456fa7475480c5"
},
{
"id":"s20",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=36392670",
"title":"How Canva saves Amazon S3 costs",
"quote":"See the Docker x Cloudflare case study where improving cache-hit ratio by 2% (by moving to R2) decreased S3 egress fee by 66%",
"summary":"Cites a concrete egress number in an S3-cost thread: a 2% cache-hit-ratio improvement from moving to R2 cut Docker's S3 egress bill by 66%. Positive, with a hard percentage.",
"publisher":"Hacker News",
"author":"ignoramous",
"date":"2023-06-19",
"claim_ids": [
"c13"
],
"quote_sha256":"cb7dec9ab50fb3df01c48c845321cc74a0bd41e8fad6307d1a0223dab5924dde"
},
{
"id":"s21",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=41753985",
"title":"WordPress Plugin Mirror Downloader (Proof of Concept)",
"quote":"All up, it would be US$5.35/month starting costs which will rise as number of WordPress plugins and Worker usage increases as outlined here. Cloudflare CDN bandwidth is free of charge, so no need to worry about egress bandwidth fees.",
"summary":"Full cost breakdown for a real 33GB WordPress plugin mirror on R2 + Workers: under $0.35/month storage, Class A/B ops inside the free quota, 765K Worker requests/day at 2.1ms median CPU, total $5.35/month. Positive, with itemized numbers.",
"publisher":"Hacker News",
"author":"3eb7988a1663",
"date":"2024-10-06",
"claim_ids": [
"c1",
"c3"
],
"quote_sha256":"c9fe6f56029571f24b9bb4168b0175c849de219c73284b0979ab13ed9b3cc194"
},
{
"id":"s22",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=47700966",
"title":"Ask HN: S3(AWS) vs R2(CF)–Which is better?",
"quote":"R2's zero egress pricing is genuinely compelling for anything serving large files publicly - media, assets, user uploads. If your use case is \"store stuff and serve it to users,\" R2 wins on cost.",
"summary":"Runs multi-region on AWS and stays on S3 because of IAM/CloudFront/ECS/Lambda integration, but says R2 wins outright when the workload is serve-to-users and bandwidth is a real line item. Mixed — a clear statement of where the egress saving does and does not pay.",
"publisher":"Hacker News",
"author":"JoshBlythe",
"date":"2026-04-09",
"claim_ids": [
"c15",
"c18",
"c4"
],
"quote_sha256":"ffeef4f6e9255e0ccbbcec9d4011425413592ea525190877c4e546616a020118"
},
{
"id":"s23",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=42257068",
"title":"Comparing AWS S3 with Cloudflare R2: Price, Performance and User Experience",
"quote":"It's not mentioned, but important to note, that R2 lacks object versioning.",
"summary":"Flags missing object versioning as an omission from the comparison. A downstream reply notes versioning and Object Lock are core malware/human-error protections; others say you must reimplement versioning yourself in a Worker. Negative.",
"publisher":"Hacker News",
"author":"kevlened",
"date":"2024-11-27",
"claim_ids": [
"c6"
],
"quote_sha256":"3040d8071c0f3d17084e85475947292bfb6997d5511e354f5753f71cea2d1420"
},
{
"id":"s24",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=33865229",
"title":"Hetzner continues its growth in the US with a new location",
"quote":"They claim $0 egress fees, but their free \"Class A operations (mutate state)\" and \"Class B operations (read state)\" have a mothly cap. After that you pay by the number. Isn't that an egress free?",
"summary":"Reader of the R2 pricing page arguing the \"$0 egress\" claim is undercut by metered Class A/B operations once the monthly free cap is exceeded. Negative — the class-ops gotcha stated plainly.",
"publisher":"Hacker News",
"author":"Archelaos",
"date":"2022-12-05",
"claim_ids": [
"c18"
],
"quote_sha256":"0e80c2b32ef5b368402dc94d00b24adb638156e9e836d7b9a76e245d09ec65e0"
},
{
"id":"s25",
"type":"hn",
"url":"https://news.ycombinator.com/item?id=42257094",
"title":"Comparing AWS S3 with Cloudflare R2: Price, Performance and User Experience",
"quote":"Is R2 egress actually free, or is it like CFs CDN egress which is \"free\" until they arbitrarily decide you're using it too much or using it for the wrong things so now you have to pay $undisclosed per GB?",
"summary":"Questions whether R2's free egress carries the same undisclosed enforcement risk as Cloudflare CDN bandwidth. Spawned a long subthread about Cloudflare terminating heavy or disfavoured users. Negative.",
"publisher":"Hacker News",
"author":"jsheard",
"date":"2024-11-27",
"claim_ids": [
"c8"
],
"quote_sha256":"53403d8f82c3986f35d3b9c7ae27d26de9c37a716987e812e71e85648d8a3ce3"
},
{
"id":"s26",
"type":"reddit",
"url":"https://old.reddit.com/r/CloudFlare/comments/1qhbrey/cloudflare_r2_let_me_serve_almost_twice_as_much/",
"title":"Cloudflare R2 let me serve almost twice as much data this month as the SEC for $10.80",
"quote":"I maintain an archive of every SEC filing, accessible via api. I store each filing in R2, compressed with zstandard. I cache egress.",
"summary":"Full SEC filing archive served from R2 with zstd compression and cached egress, total monthly cost $10.80 while serving roughly twice the SEC's own volume. Positive with a real number, the clearest R2-vs-S3-egress datapoint found.",
"publisher":"Reddit",
"author":"u/status-code-200",
"date":"2026-01-19",
"claim_ids": [
"c18"
],
"quote_sha256":"8a7c6a3e7f0d73a7ab9e5c77a96d975f6d6d25cd65261ceb15072067bc84fb32"
},
{
"id":"s27",
"type":"runtime_receipt",
"url":"https://miscsubjects.com/img/up/cloudflare-os-r2-hero-card.png",
"title":"Live R2 object headers",
"quote":"cache-control: public, max-age=31536000",
"summary":"First-party production receipt: a 51,205-byte public object returned the cache header shown, with the command and timing published in the article.",
"publisher":"miscsubjects.com",
"author":"",
"date":"2026-07-26",
"claim_ids": [
"c13",
"c14",
"c16",
"c17"
],
"quote_sha256":"42afdb8693a8354af29ef443266e79bb136c5e8efb7df251c2161bfd75c92d65"
}
],
"claims": [
{
"id":"c1",
"text":"R2 charges for stored bytes and Class A and B operations, but not internet egress.",
"section":"Zero egress is real; the meter is on the operations",
"tier":"system",
"source_ids": [
"s1",
"s19",
"s21"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c2",
"text":"At the published rates, the worked 1 TB stored and 10 TB served workload costs $18.45 on R2 and $923.00 on S3.",
"section":"Serving 10 TB a month: $18.45 on R2, $923.00 on S3",
"tier":"system",
"source_ids": [
"s1",
"s15"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified"
},
{
"id":"c3",
"text":"R2 operation rates are lower than the compared S3 Standard request rates, so operations do not claw back the egress saving in the worked workload.",
"section":"Serving 10 TB a month: $18.45 on R2, $923.00 on S3",
"tier":"system",
"source_ids": [
"s1",
"s15",
"s21"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c4",
"text":"For a 100 TB cold archive consumed inside AWS, R2 Infrequent Access costs $1,000 monthly while S3 Glacier Flexible Retrieval costs $360 and Deep Archive costs $99.",
"section":"The workload where S3 wins is the one you never read",
"tier":"system",
"source_ids": [
"s1",
"s15",
"s22",
"s5"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c5",
"text":"For a 1 GB object, R2 Infrequent Access becomes cheaper than Standard only below about one read every two months, before considering its 30-day minimum.",
"section":"Infrequent Access pays only below about one read every two months",
"tier":"system",
"source_ids": [
"s1",
"s5",
"s6"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified"
},
{
"id":"c6",
"text":"R2 does not implement S3 bucket versioning or S3 Object Lock operations; bucket locks prevent overwrite and deletion but do not retain prior versions.",
"section":"R2 will not keep the old version of an object",
"tier":"system",
"source_ids": [
"s23",
"s4",
"s7"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c7",
"text":"Content-addressed writes plus a current-pointer object provide application-level versioning at the cost of an extra read and retained old objects.",
"section":"R2 will not keep the old version of an object",
"tier":"system",
"source_ids": [
"s16",
"s3",
"s6"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c8",
"text":"Cloudflare's terms permit large-file delivery through paid Developer Platform services and reserve temporary rate limiting for undue network burden.",
"section":"The free-egress trust question, answered from the terms",
"tier":"system",
"source_ids": [
"s1",
"s14",
"s25"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c9",
"text":"R2 writes and deletes are strongly consistent, while listing is a Class A operation and reads are Class B.",
"section":"Every call, and which meter it hits",
"tier":"system",
"source_ids": [
"s1",
"s2",
"s3"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified"
},
{
"id":"c10",
"text":"A single-part R2 upload is limited to 5 GiB; larger objects require multipart upload and top out just below 5 TiB.",
"section":"Every call, and which meter it hits",
"tier":"system",
"source_ids": [
"s10",
"s3"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified"
},
{
"id":"c11",
"text":"Presigned URLs authorize one named operation on one object until expiry without exposing the signing credentials.",
"section":"Every call, and which meter it hits",
"tier":"system",
"source_ids": [
"s16",
"s9"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c12",
"text":"A custom domain is the production public-bucket path; r2.dev is rate-limited and documented for non-production use.",
"section":"Serving an object publicly, and the header that decides your bill",
"tier":"system",
"source_ids": [
"s10",
"s17",
"s8"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c13",
"text":"The production public-object handler maps the URL path to the R2 key and sends a one-year public cache lifetime.",
"section":"Serving an object publicly, and the header that decides your bill",
"tier":"system",
"source_ids": [
"s20",
"s27",
"s3"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"observed + specified + externally attested"
},
{
"id":"c14",
"text":"Moving oversized revision payloads to R2 reduced one article's D1 revision index from 2,068,258 bytes to 206,362 bytes while preserving revision retrieval.",
"section":"When a row outgrows D1, the bytes move to R2 and the row keeps a pointer",
"tier":"system",
"source_ids": [
"s12",
"s27"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"observed + specified"
},
{
"id":"c15",
"text":"The storage choice follows the access pattern: R2 for public blobs, S3 Glacier for captive cold archives, KV for small read-mostly values, D1 for queries, and Durable Objects for serialized state.",
"section":"Choosing between R2, S3, KV, D1 and Durable Object storage",
"tier":"system",
"source_ids": [
"s10",
"s11",
"s12",
"s13",
"s22"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"specified + externally attested"
},
{
"id":"c16",
"text":"The measured production bucket held 41,809 objects and 3,904,595,147 bytes across 62 list pages on 2026-07-26.",
"section":"How the numbers on this page were measured",
"tier":"system",
"source_ids": [
"s27"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"observed"
},
{
"id":"c17",
"text":"Six production PUTs had a 686 ms median and six GETs had a 136 ms median through the Worker from the San Jose edge.",
"section":"How the numbers on this page were measured",
"tier":"system",
"source_ids": [
"s18",
"s27"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"observed"
},
{
"id":"c18",
"text":"Published operators report a $5.35 monthly WordPress mirror and a $10.80 monthly SEC archive on R2, while another operator stays on S3 for cold and AWS-integrated workloads.",
"section":"Serving 10 TB a month: $18.45 on R2, $923.00 on S3",
"tier":"system",
"source_ids": [
"s22",
"s24",
"s26"
],
"why_material":"This changes the storage choice, bill, implementation, or failure response.",
"who_claims":"Opus 5 (Claude Code)",
"evidence_status":"externally attested"
}
],
"widgets": [
{
"type":"stat",
"value":"$18.45",
"label":"R2 total for the worked 1 TB stored and 10 TB served month"
},
{
"type":"stat",
"value":"$923.00",
"label":"S3 total for the same worked month in us-east-1"
},
{
"type":"stat",
"value":"2.475B",
"label":"paid Class B calls needed to equal the worked S3 egress line"
},
{
"type":"stat",
"value":"<0.5",
"label":"reads per month where a 1 GB object favors Infrequent Access"
},
{
"type":"stat",
"value":"41,809",
"label":"objects in the measured production bucket"
},
{
"type":"stat",
"value":"3.64 GiB",
"label":"bytes in the measured production bucket"
},
{
"type":"quote",
"text":"It's not mentioned, but important to note, that R2 lacks object versioning.",
"cite":"kevlened, Hacker News"
},
{
"type":"note",
"title":"The boundary",
"text":"Choose R2 for bytes served to users. Choose a colder S3 tier when the archive stays inside AWS and is almost never read."
}
],
"type":"article",
"updated":"2026-10-08T11:33:04.843Z",
"version":1,
"hash":"5487bf416de20158dff5edb04de69fd0601a9e133d00aa0339bcde090d165927",
"styling": {
"scope":"shared",
"how":"no value on the page is set by hand: each comes from this theme, and each theme value becomes the CSS variable named beside it. PATCH http://google-preview.miscsubjects.com/api/jarticles/theme changes them.",
"widget_style": {
"what":"every widget may carry style: {…}; these are the only keys it reads",
"rotate":"degrees, a number",
"offset_x":"pixels, a number",
"offset_y":"pixels, a number",
"pulse":"true to pulse"
},
"theme": {
"color": {
"page_bg":"#f5f5f7",
"sheet_bg":"#ffffff",
"ink":"#1d1d1f",
"soft":"#424245",
"muted":"#6e6e73",
"dim":"#86868b",
"line":"#d2d2d7",
"accent":"#0071e3",
"accent_soft":"rgba(0,113,227,0.08)",
"link":"#0066cc",
"selection":"rgba(0,113,227,0.18)",
"widget_bg":"#f5f5f7",
"widget_border":"#d2d2d7",
"card_bg":"#ffffff",
"code_bg":"#f5f5f7",
"json_bg":"#161b19",
"json_ink":"#e6e1d4",
"json_key":"#7fd3c3",
"json_string":"#e9c46a",
"json_number":"#f4a261",
"json_bool":"#c792ea",
"json_null":"#928d7e",
"json_punct":"#6b6759",
"json_bar":"#0e1512",
"kind_badge_bg":"#0e6e60",
"kind_badge_ink":"#ffffff"
},
"color_dark": {
"page_bg":"#000000",
"sheet_bg":"#1d1d1f",
"ink":"#f5f5f7",
"soft":"#d2d2d7",
"muted":"#a1a1a6",
"dim":"#86868b",
"line":"#424245",
"accent":"#2997ff",
"accent_soft":"rgba(41,151,255,0.12)",
"link":"#2997ff",
"selection":"rgba(41,151,255,0.25)",
"widget_bg":"#2c2c2e",
"widget_border":"#424245",
"card_bg":"#1d1d1f",
"code_bg":"#2c2c2e",
"json_bg":"#0a0d0c",
"json_ink":"#e6e1d4",
"json_key":"#7fd3c3",
"json_string":"#e9c46a",
"json_number":"#f4a261",
"json_bool":"#c792ea",
"json_null":"#757062",
"json_punct":"#5d665f",
"json_bar":"#060807",
"kind_badge_bg":"#4fc1ab",
"kind_badge_ink":"#0b0f0d"
},
"font": {
"display":"-apple-system,BlinkMacSystemFont,\"SF Pro Display\",\"SF Pro Text\",\"Helvetica Neue\",Helvetica,Arial,sans-serif",
"body":"-apple-system,BlinkMacSystemFont,\"SF Pro Display\",\"SF Pro Text\",\"Helvetica Neue\",Helvetica,Arial,sans-serif",
"mono":"ui-monospace,SFMono-Regular,\"SF Mono\",Menlo,Consolas,monospace",
"google_fonts":""
},
"size": {
"body":"17px",
"small":"17px",
"eye":"17px",
"lead":"17px",
"h1":"52px",
"h2":"34px",
"h3":"22px",
"byline":"17px",
"h1_measure":"none",
"code":"17px",
"json":"17px",
"widget_title":"17px"
},
"leading": {
"body":"1.7",
"head":"1.18",
"lead":"1.5",
"json":"1.6"
},
"weight": {
"display":"700",
"head":"700",
"body":"400",
"strong":"700",
"eye":"700"
},
"tracking": {
"eye":"0.14em",
"display":"-0.03em",
"body":"-0.006em",
"badge":"0.08em"
},
"layout": {
"sheet_width":"1000px",
"text_width":"880px",
"gutter":"16px",
"sheet_padding":"56px 64px 64px",
"sheet_padding_mobile":"24px 18px 40px",
"sheet_margin":"28px auto 72px",
"block_gap":"1.15em",
"widget_gap":"28px",
"grid_gap":"14px"
},
"border": {
"sheet":"0px solid",
"sheet_radius":"30px",
"widget":"1px solid",
"widget_radius":"24px",
"card_radius":"24px",
"badge_radius":"999px",
"rule":"1px solid",
"code_radius":"18px",
"accent_bar":"3px"
},
"shadow": {
"sheet":"0 1px 1px rgba(0,0,0,.02),0 6px 26px rgba(0,0,0,.05)",
"widget":"none",
"card_hover":"0 10px 28px -16px rgba(28,27,23,0.35)"
},
"motion": {
"hover":"160ms ease"
}
}
},
"page":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2",
"json":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2.json",
"markdown":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2.md",
"theme":"http://google-preview.miscsubjects.com/article-theme.json",
"calls": [
{
"what":"this article as a page (no key)",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2",
"headers": {}
},
{
"what":"this article as its object (no key)",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2.json",
"headers": {}
},
{
"what":"this article as Markdown (no key)",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/a/cloudflare-os-r2.md",
"headers": {}
},
{
"what":"the object with its hash, drafts too",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)"
}
},
{
"what":"one piece and that piece’s hash",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2/at?path=facts",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)"
}
},
{
"what":"grep: every key or value that matches, with the path to change it",
"method":"GET",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2/grep?q=owner",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)"
}
},
{
"what":"change pieces (set, merge, delete, append, insert, move); if-match is the hash",
"method":"PATCH",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)",
"content-type":"application/json",
"if-match":"<hash from the read>"
},
"body": {
"ops": [
{
"op":"set",
"path":"facts.example",
"value":1
}
]
}
},
{
"what":"replace the whole object",
"method":"PUT",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)",
"content-type":"application/json",
"if-match":"<hash>"
},
"body": {
"slug":"cloudflare-os-r2",
"title":"…"
}
},
{
"what":"fetch every source, hash what came back and check the quote is in it",
"method":"POST",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cloudflare-os-r2/verify",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)",
"content-type":"application/json"
},
"body": {}
},
{
"what":"an Obsidian-style command",
"method":"POST",
"url":"http://google-preview.miscsubjects.com/api/jarticles/cli",
"headers": {
"x-sheets-key":"$(cat /Users/cyrusmassoumi/.misc-sheets-key)",
"content-type":"application/json"
},
"body": {
"command":"backlinks",
"file":"cloudflare-os-r2"
}
}
]
}