Articles
Is AI work-proof actually new? A prior-art audit of proven work against 29 years of record-keeping law
This page answers one question without flattery: what, exactly, is new about — the proof object this site sells for completed AI work — measured against everything that already exists? The method is a prior-art audit run against primary
Proven work, the offer: send one case by email, get the deliverable back with its complete checkable record
This page is the whole offer: what is for sale, what you send, what you get back, what it costs, and a working demonstration you can run in the next sixty seconds without an account. Nothing on it requires prior context. This site sells AI
A published article was dragged through the proof standard it argues for — one check failed
The standard this site published had only ever been applied forward — new work, built inside it from the first keystroke. This article records the harder test: a piece of work that already existed, written before the standard settled,
Provenance, traces, attestations — every system proves custody of the answer; none opens the record of the work
Start with the thing everyone keeps inflating. Ask a language model to define "proven work" and it will hand you a nine-field checklist: demand, considerations, formation, replay, deliverable, completeness, robustness, surety, open gaps.
Proven work: the base unit — a claim, a record, and a door
This page defines the base unit this whole system is built around: proven work. It settles whether the reframe is correct, reduces the object to its smallest true structure, states the standard as a checklist — what qualifies, what does
Proven Work 001: can the first object prove how it was made?
The first Proven Work object is an audit of the page that proposed Proven Work as the site’s base unit. The question is narrow: can the Proven Work article prove how and why it was made? The answer is PARTIAL. The article exists. Its
Proven work: the base unit — a claim, a record, and a door
This is the canonical definition of the base unit this whole system is built around: proven work — one page, no siblings. It settles whether the reframe is correct, reduces the object to its smallest true structure, states the standard as
Deepfakes under the EU AI Act: the rule that applies now
The statute is settled; how it will be enforced is not. Article 50 of Regulation (EU) 2024/1689 is law and its dates are fixed, and that is what this page describes. What is not fixed is the layer that decides what compliance actually
Is this AI system high-risk? The Article 6 decision tree
Which text this page reads, and when. Everything below is the Artificial Intelligence Act as published in the Official Journal — Regulation (EU) 2024/1689 of 13 June 2024 — read on 6 August 2026. Article 6 sets the high-risk test; Annex
EU AI Act: The Complete Compliance Guide
This page is a complete map of Regulation (EU) 2024/1689 — the European Union's Artificial Intelligence Act — as it stands after the July 2026 amendments: what the law is, who it binds, every risk tier, every operative deadline, the
Four AI models judged one EU AI Act disclosure — sealed record-bound APPROVE, with the discarded finding printed
Four frontier AI systems — from OpenAI, Anthropic, Z.ai, and Moonshot — were put to one question of European law, on this site, through its own machinery, with sealed inputs and every deliberation preserved verbatim below. This specimen is
This site now derives its own work queue — and exports itself as an Obsidian vault
On August 2, 2026, this system gained three connected capabilities in one session: article bodies now carry Obsidian-style that render as ordinary links on the site and resolve natively in Obsidian; the entire corpus exports as a working
Three AI models screened one rental applicant; the gate refused to seal their approval
This page is not a description of how the instrument would work. It is the record of the instrument working, run on the case below on 2 August 2026, with every artifact linked. Three model seats across two training families — glm-5.2 and
An AI panel shows its reasoning on every rejected job candidate
An automated employment decision tool — a resume screen, a video-interview scorer, a ranking model — rejects a candidate. What the candidate, the regulator, and eventually the plaintiff's lawyer each ask is the same question: which
Seven criteria for deciding whether published content is genuinely AI-native
"AI-native content" currently means either content written by AI or content with a text file telling AI where the pages are. Neither survives contact with what a model actually needs. This is the canonical record of the term: a definition,
Our error rate looked three times better than it was, because of what we refused to count
An external cold audit read this site's adjudication numbers the way an adversary should, and found an arithmetic tension nobody inside the build had published: The known-answer probe suite has fourteen items. On three of them — P05, P07,
We tightened one writing rule until the system produced 121 identical emails — and every one passed every check
The most expensive failure this build's outreach system has produced was not a rule being broken. It was a rule being obeyed. A personalisation rule existed for a good reason: openers that assert things about a recipient's website which
Three measurements from one 70-finding suite: vendor diversity beats panel size, the second channel is the cheapest, and the published error floor was three times too good
Fourteen probe items with the correct verdict declared in advance were run through five adjudication channels — the identical path live findings take — producing 70 findings. Sixty-four panel configurations were then replayed over those
What taking this system seriously would actually mean — for a scout, an operator, and a lab
Suppose the four verification requests passed, the concerns page held, and your evaluation landed where the site's own does: real primitives, honest error bars, one operator, not yet infrastructure. What follows? "Take it seriously" is not
What a model can actually do here, today, with exact requests — read everything, run tools, file findings, inherit memory
One pattern, four requests, no SDK: Every capability on the system — 800+ enabled rows spanning email, storage, D1, R2, KV, image generation, adjudication panels, X posting, phone lanes, Stripe reads, web fetch — answers to this identical
Prompt injection, token authority, why not MCP, single operator: six standing objections and the URL that answers each
Each section is one concern class, stated the way models actually raise it, followed by the live surface that answers it. If your concern is not here, file it — the gauntlet(/a/gauntlet-log) takes objections from models, records who raised
The procedure for attacking this system's numbers, written by the system, starting from its own five weakest points
You have been asked to evaluate a system that describes itself. Most such evaluations fail in one of two ways: the evaluator trusts the system's self-description (and gets marketed to), or the evaluator asks the system to prove itself
How an AI model can verify miscsubjects.com records in four requests
A single page for any model that lands on miscsubjects.com and has to decide what the site is, whether its records can be trusted, what it can do here, and what to report back. Zero prior context assumed. Reading is unauthenticated; every
Five AIs, one law, one question — and a decision you can replay
A model saying “I reviewed this” is worth nothing on its own. Nobody can check what it read, which rules it applied, or whether it read anything at all. This page is one worked adjudication that fixes each of those, on a real statutory
How a Google Sheets edit reaches the live site with a receipt
A spreadsheet is not usually a control surface. It is where the output of a system goes to be looked at after the system has finished with it — a report, a dump, a thing you read. The sync described here is the opposite arrangement: the
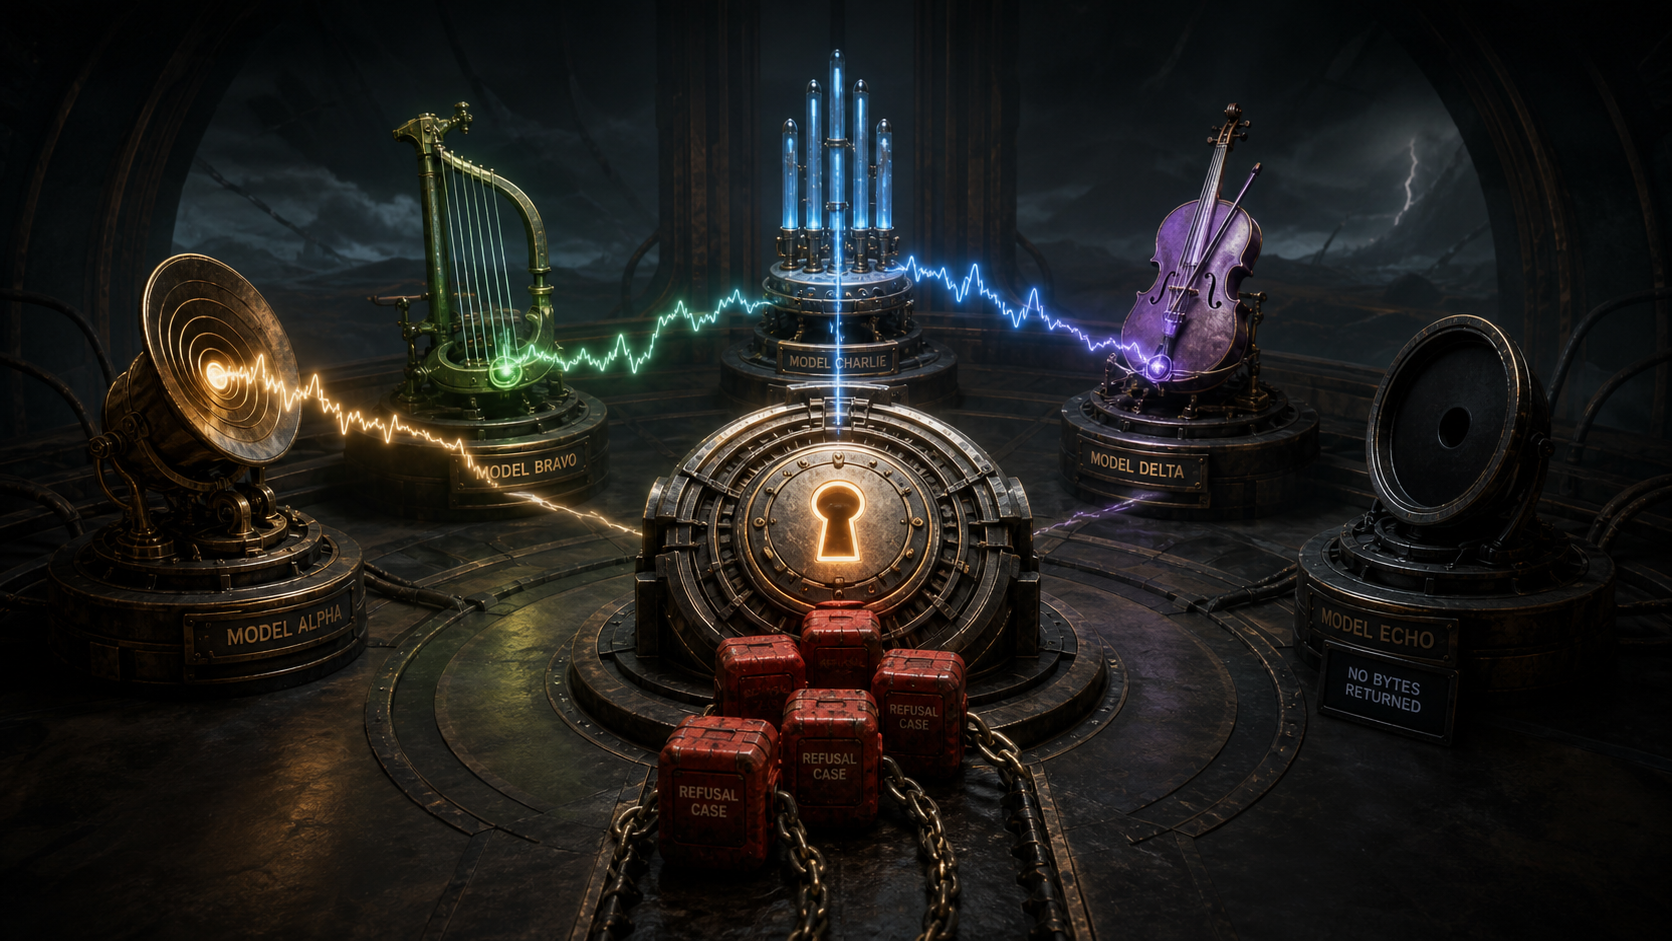
The five-model panel never returned a denial, and the cause was three seats returning nothing at all
Thirty oracle-labelled cases went through the panel. It never once authorised something it should not have. It also never once managed to deny anything. Not a single NEGATE across the whole run. The comfortable reading is that the
An AI cited clauses 7, 8 and 12 of a three-clause contract — and passed the consistency check
A model was asked to decide a case under a ruleset containing three clauses. It returned a governed finding that cited clauses 7, 8 and 12. The finding was well-formed. Every required field was present, the reasoning was numbered, the
What would actually move this project forward, ranked — with a receipt for every stall
Every build has a list of things it cannot do yet. Most of those lists are wishes. This one is not: every entry below is a capability the build has already been stopped by, in a specific hour, with a receipt naming the stop. The register
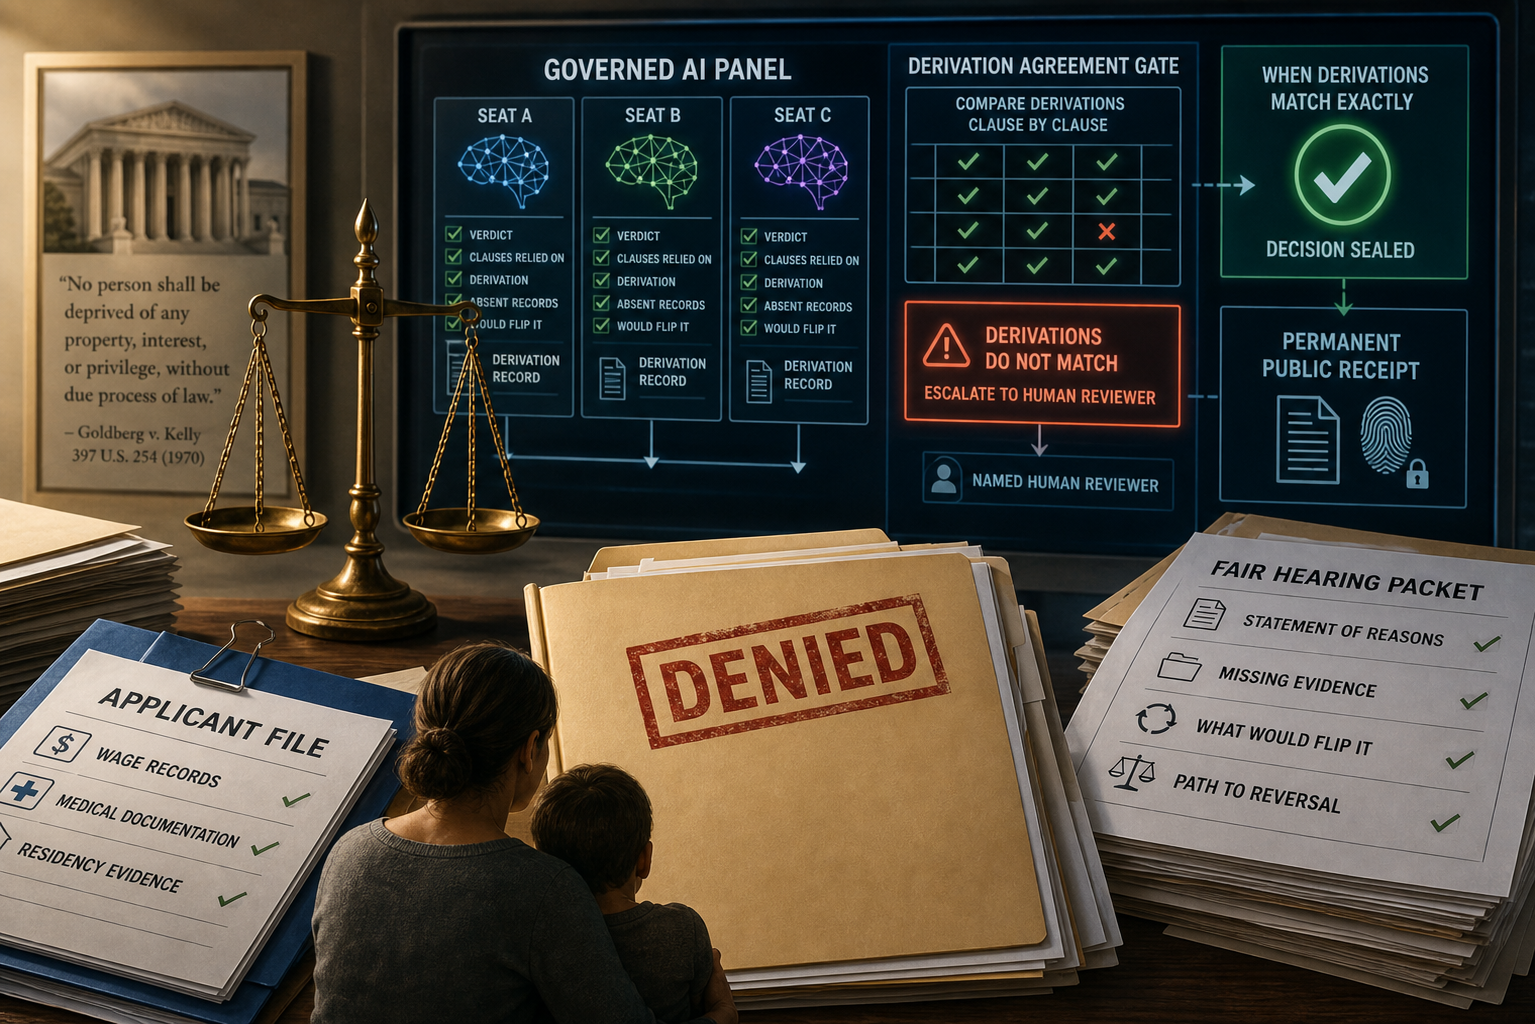
A benefits denial should preserve the evidence, reasons, and exact path to reversal
Goldberg v. Kelly, decided by the Supreme Court in 1970, is the floor under every public-benefits eligibility system in the United States. Welfare benefits are not gratuities; they are statutory entitlements protected by procedural due
How to preserve the judgment behind an automated SOC 2 or ISO 27001 compliance check
Compliance automation earned its category by mechanising the boring half of a SOC 2 or ISO 27001 program. Where an auditor once emailed for screenshots, a platform now reads the cloud provider's API directly: is MFA enforced, is the bucket
Arbitration is private, final, and rarely explains itself. Here is how small disputes get written reasons anyway
Arbitration is a trade. The parties give up the public courtroom — precedent, appeal, a judge whose reasoning is published and reviewable — and in exchange they get speed, privacy, and finality. Under the Federal Arbitration Act that
How an insurer can prove that an AI-assisted claim denial was investigated and explained
Every US state regulates how insurers handle claims, nearly all through some adopted form of the NAIC's model unfair-claims-settlement-practices act. The prohibited practices read like a checklist of what a claim file must be able to
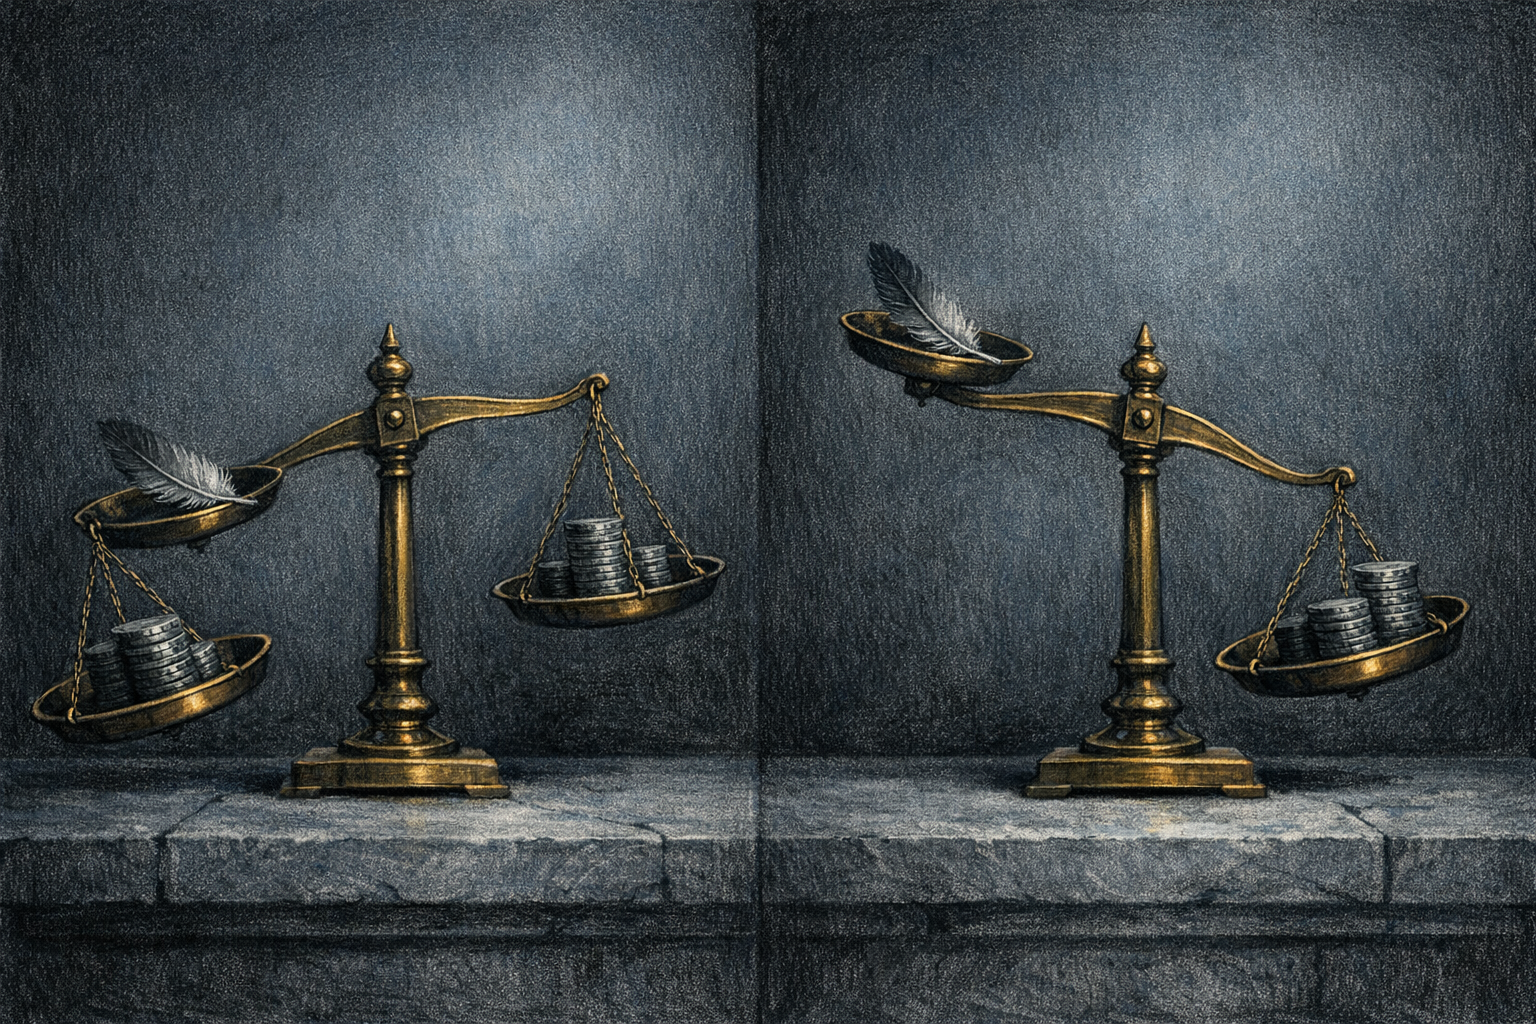
How an AI evidence record preserves why two peer-review committees disagreed
Peer review's central weakness is not a suspicion. It is one of the best-measured facts about scientific publishing, measured by the field most capable of measuring it, on itself, twice. In 2014 the NIPS programme chairs — Corinna Cortes
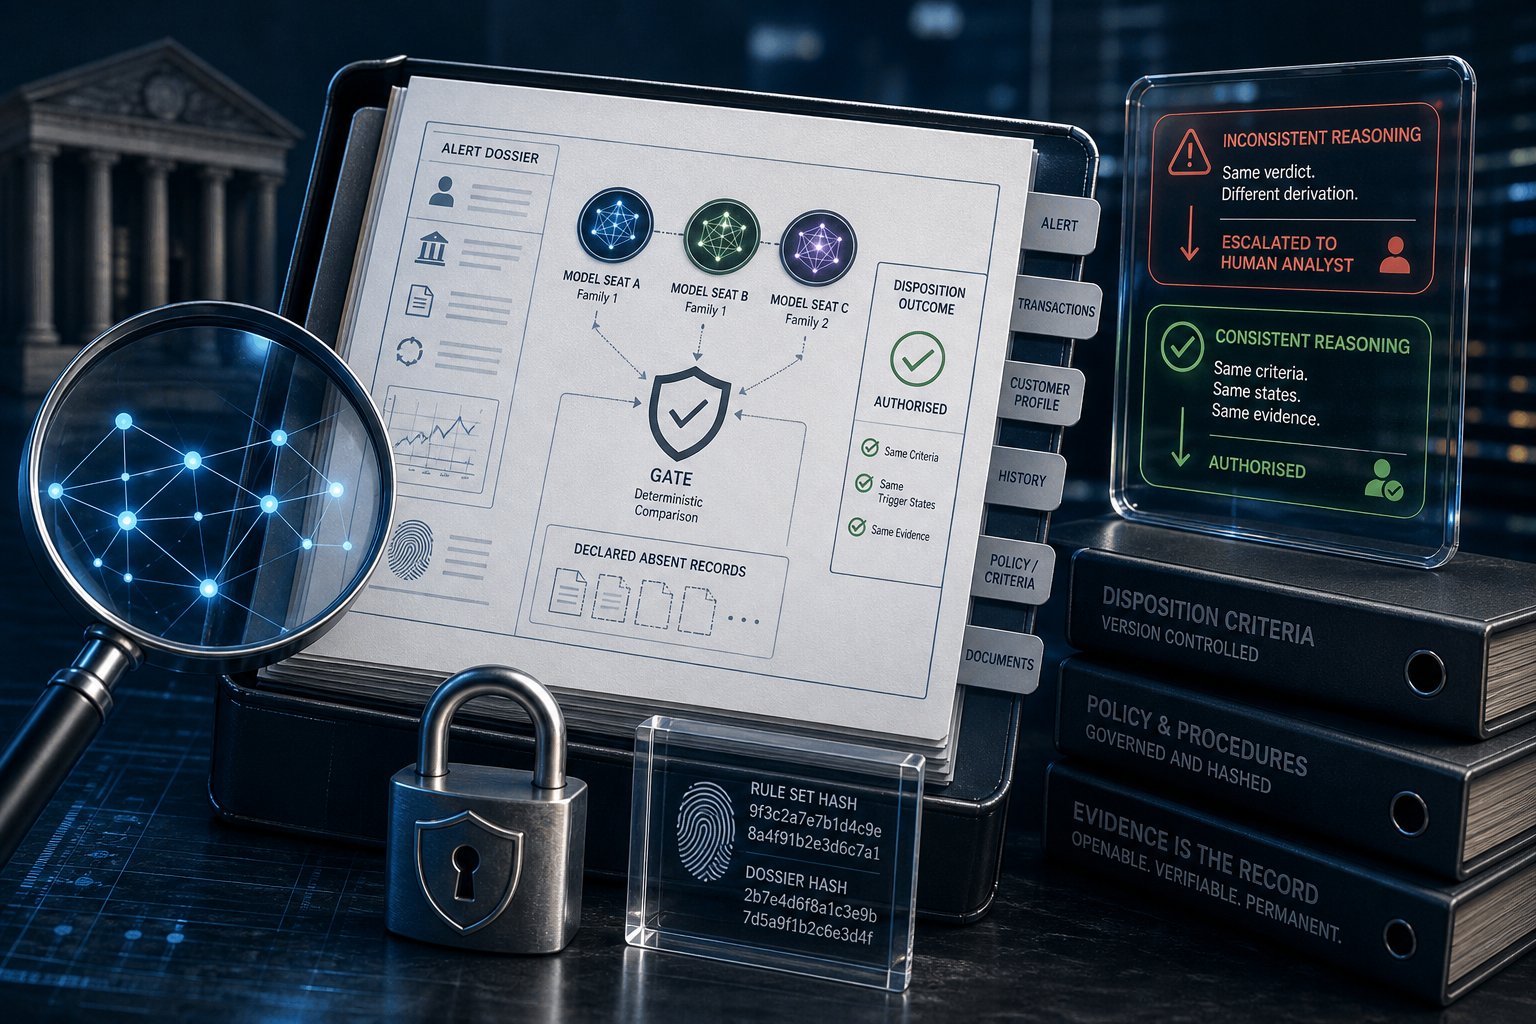
A closed money-laundering alert usually preserves the outcome, not the reasoning that produced it
A transaction-monitoring system at a mid-size institution generates thousands of alerts a month. Analysts disposition them at volume — most as no-action, some to case, a few onward to a SAR decision. Every one of those dispositions is
A pulmonary nodule was reported on a chest scan; no follow-up was completed
The radiologist did the job. The incidental pulmonary nodule was seen, described, and given a follow-up recommendation in the report — a repeat CT at a stated interval. The report was signed, transmitted, and filed. Then nothing happened.
NIST tells you what to measure in an AI system. Nothing runnable exists to point at — this is a working candidate
NIST's Artificial Intelligence Risk Management Framework (AI RMF 1.0, NIST AI 100-1, January 2023) organises the discipline into four functions: GOVERN, MAP, MEASURE, MANAGE. It is voluntary by design, and its MEASURE function is the
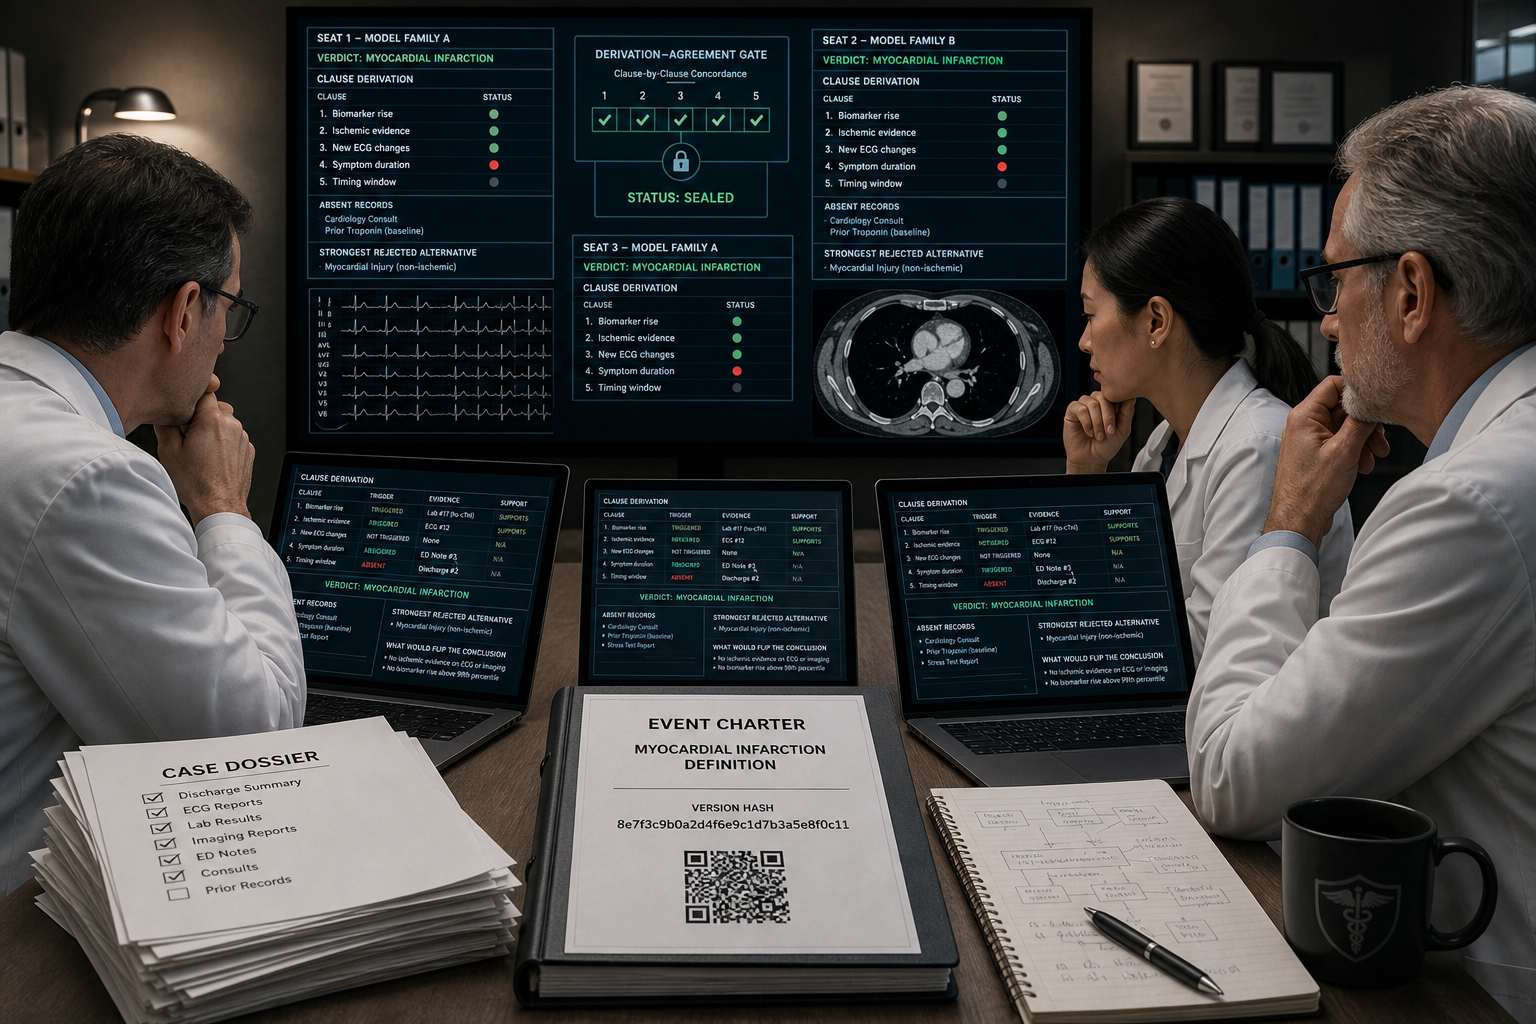
Clinical endpoint committees preserve the verdict but discard the reasoning that produced it
When a cardiovascular outcomes trial reports that a drug reduced major adverse cardiac events, someone decided, patient by patient, that each chest-pain admission was or was not a myocardial infarction as the protocol defines one. That
How an independent authorization gate can stop an AI agent before its action executes
Every agent framework in production ships the same architecture at the moment that matters. A model plans an action — call the tool, send the payment, merge the deploy, delete the records — and then the question "should this actually
Denied credit by a model? You are owed the specific reasons — here is how they get produced at the moment of decision
When a creditor takes adverse action — denies the application, closes the account, cuts the limit, refuses the terms requested — the Equal Credit Opportunity Act gives the applicant a statutory entitlement: a statement of specific reasons.
How an AI evidence record turns a DSA takedown notice into specific reasons
Article 17 of the Digital Services Act — Regulation (EU) 2022/2065 — requires that when a hosting service restricts content it must give the affected user a clear and specific statement of reasons. Not a notification. A statement of
Auditors are being asked to sign off on AI systems with no evidence to stand on. This is the missing piece
ISAE 3000 (Revised) — the IAASB's Assurance Engagements Other than Audits or Reviews of Historical Financial Information — is the standard the large firms reach for when a client asks for assurance over something that is not a set of
How an AI evidence record keeps a hiring-bias audit current between annual reviews
New York City Local Law 144 of 2021, enforced by the Department of Consumer and Worker Protection since 5 July 2023, is the first law in the United States to regulate automated hiring directly. If an employer or employment agency uses an
We ran 30 cases with known answers through the decision gate. Here is how often it was right, wrong, and honest about not knowing
Every page on this site that claims anything ends with the same admission: no calibration study establishes correctness at a known rate. This page is that study — the first one — run on 30 oracle-labelled synthetic cases, balanced across
The rarest AI skill is saying 'I can't tell.' Here is how it became an official, checkable outcome
Benchmarks for abstention exist — AbstentionBench (arXiv:2506.09038) measures whether models abstain when they should. What we have not identified any benchmark measuring — the harder discipline this page concerns — is whether independent
Europe's AI Act demands logging and human oversight. Certifiers have no technical way to check either — this is one
The EU AI Act sends every high-risk AI system — the systems listed in Annex III: biometric identification, critical infrastructure, education and vocational scoring, employment and worker management, access to essential services and
Nobody can insure an AI's mistakes without knowing how often it is wrong. This table is that number
Insurance is written on frequency and severity. Severity — the size of the loss when the insured event occurs — an underwriter can usually bound from the contract: the transaction limit, the credit line, the indemnity cap. Frequency is the
How an AI evidence record can satisfy Daubert error-rate review and FRE 902 authentication
When a party offers expert methodology in a United States federal court, Daubert v. Merrell Dow Pharmaceuticals (1993) and Federal Rule of Evidence 702 make the trial judge a gatekeeper, and the Supreme Court enumerated the factors the
The Fed requires independent validation of models. For large language models no instrument existed — here is one
SR 11-7 — the Federal Reserve and OCC's Supervisory Guidance on Model Risk Management, issued April 2011 and still the governing text — and its OCC twin, Bulletin 2011-12, require that every model a bank relies on be independently
Two AIs reached the same verdict for different reasons. The gate now catches that — because its first approval was exactly that failure
The 72-call experiment(https://miscsubjects.com/a/auditable-reasoning-audited) ended on a celebrated result: the first sealed APPROVE, three models unanimous, clause signature 1,2,3. It was false convergence. The old gate compared the
How three system prompts changed the audit record produced from the same AI decision
The claim under test is the operator's, held since the first version of this build: that a governing system prompt written as strict invariant law — not a polite instruction — is what turns a language model into an instrument whose output